
TL;DR
- I-JEPA predicts learned features of hidden image regions from visible context, rather than reconstructing RGB pixels. A full-image EMA teacher supplies targets while gradients train the context encoder and predictor.
- Multi-block masking and positional queries define what can be seen and what must be predicted. Actual retained patch indices matter, especially when targets overlap or sampler fallbacks change context exclusion.
- The paper prints a squared L2 objective; the released code uses mean Smooth L1. The runnable training reference follows the released implementation and checks the update path on small random inputs.
- The pretrained explorer separately shows saved ViT-H/14 checkpoint predictions with source and checkpoint digests. Feature agreement and hidden-pixel leakage checks do not by themselves establish semantic recognition.
- Published full-label linear evaluation and 1% label results use different adaptation protocols. Keep backbone, resolution and evaluation settings attached when comparing representation quality.
Paper Overview
For the foundations, start with visual representations and image patch embeddings. The self-supervised learning and target encoder / EMA pages explain how the training targets and parameter updates below fit together.
What should a model predict when part of an image is hidden? MAE predicts pixels. Invariance-based methods such as DINO learn matching representations of differently augmented views. I-JEPA instead predicts the features of hidden image regions, using the visible region as context. A second encoder supplies the feature targets during training.
I-JEPA means Image-based Joint-Embedding Predictive Architecture. Its three components are a context encoder, a narrow predictor, and a target encoder updated through an exponential moving average (EMA). The context encoder sees visible patches; the target encoder sees the full image. The predictor must bridge that information gap in representation space. No RGB decoder is needed for this training objective.
The CVPR 2023 paper reports 79.3% ImageNet-1K linear evaluation for ViT-H/14 at 224 resolution, and 81.1% for ViT-H/16 at 448 resolution. With 1% of ImageNet labels, those models reach 73.3% and 77.3%, respectively. These are distinct evaluation protocols: full-label linear evaluation freezes the encoder; the 1% comparison allows each method its best fine-tuning or linear-probing approach. Final paper, Tables 1–2.
Predict Features, Not Pixels
Pixel reconstruction asks a model to preserve enough information to reproduce colors, edges, and textures. Feature prediction changes the target: the teacher’s representation can encode useful structure without requiring the predictor to reconstruct every pixel. That does not make every feature automatically semantic, or make texture irrelevant. The paper evaluates both classification and lower-level tasks such as object counting and depth prediction.
The printed paper defines a squared feature-distance objective, averaged over target blocks:
Here B_i contains the patch indices of target block i, \hat h_j^{(i)} is its predicted feature, and \operatorname{sg} stops gradients through the teacher. The printed expression sums squared differences over patches and feature coordinates, then averages blocks. The released implementation instead uses Smooth L1 with β = 1 and a mean reduction. The Implementation section keeps that distinction explicit and follows the released code.
The following comparison uses one photograph and hidden region to explain the two prediction spaces. The feature bars and reconstructed crop are illustrative, not measured model output; the two methods use different masks during actual training.
Abstract prediction vs pixel reconstruction
Same missing region.
Different learning targets.
Follow the colored boxes to see what each model predicts and what that prediction is compared against.
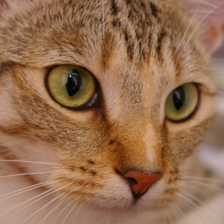
One image. One hidden region.
The visible patches provide context. The two objectives define different targets for the missing region.
Highlighted area = learning target
I-JEPA
Predict teacher features
Prediction
Learning target
Visible patches
Full image
Context encoder
Teacher encoder
No gradients
Predictor
Select region
Predicted features
Feature coordinates
Teacher features
Feature coordinates
The predictor learns to match representations from the full-image teacher. The teacher follows the context encoder through an EMA update.
MAE
Reconstruct masked pixels
Prediction
Learning target
Visible patches
Full image
Encoder
Original pixels
Decoder
Select region
Predicted pixels
RGB patch
Original pixels
RGB patch
The decoder learns to match the pixels of the original hidden patch. Reconstruction error is evaluated at masked positions.
Conceptual comparison: feature bars and reconstructed pixels are illustrative. The shared mask explains the objectives; actual I-JEPA and MAE training use different masking recipes.
Multi-Block Masking Strategy
I-JEPA samples four target blocks with scale 0.15–0.2 and aspect ratio 0.75–1.5. These blocks are sampled independently and may overlap each other. It also samples one large context rectangle with scale 0.85–1.0, then removes positions covered by the targets. The visible context is therefore the retained portion of that rectangle, rather than every patch outside the targets.
Large target blocks reduce the usefulness of simply interpolating from adjacent pixels. A spatially distributed context can supply information about other parts of an object or scene. The paper’s masking ablations support this combination; they do not establish that every prediction requires object recognition.
The released sampler has a practical fallback: after repeated failed attempts to keep enough context, it can relax target exclusion. Batch collation also truncates masks to a common retained length. A rectangle alone therefore does not tell us exactly which indices reached the encoder. The runnable reference and saved explorer cases retain actual indices and reject context–target overlap.
Multi-Block Masking Strategy
Sample four target regions, then inspect which patches remain outside their union. Select a target to see its extent; shared patches can belong to more than one block.
Four target blocks
Targets are separate prediction cases. Overlap does not merge them into one block.
Visible target complement
A shared patch is hidden once in this view, even when several target blocks include it.
- Visible
- 31patches
- Hidden
- 33patches
- Shared
- 11patches
The I-JEPA Pipeline
The context encoder is a Vision Transformer. It divides the input into non-overlapping patches, adds fixed positional embeddings, and gathers visible tokens before self-attention. The released encoder uses patch features without a CLS token. Excluding hidden patches before attention prevents their pixel content from contributing to context features.
For each target block, the predictor receives those context features and a sequence of queries. Each query combines one shared learned mask token with the positional embedding of a target patch. A narrow transformer predicts that block’s features, then projects them back to the encoder width. The ViT-H/14 recipe uses a 12-layer predictor with width 384, while the encoder features have width 1280. Different target blocks are separate prediction cases, even when their patch indices overlap.
The teacher processes the full image. The released loop layer-normalizes its features before gathering target positions. Context encoder and predictor parameters receive gradients; teacher parameters follow the updated context encoder:
The released recipe increases \tau linearly from 0.996 toward 1.0. EMA, stop-gradient, architectural asymmetry, and masking together form the learning setup; EMA alone is not a general guarantee against representation collapse.
I-JEPA avoids an extensive augmentation pipeline designed to match multiple views. It still preprocesses images: the released ViT-H/14 training recipe uses random resized crops and normalization, with color distortion, blur, and horizontal flips disabled. “No view-invariance augmentations” is more precise than “no augmentation.” The next diagram is a synthetic illustration of the data flow.
I-JEPA Training Pipeline
Follow visible context through prediction while the full-image teacher supplies the targets. Play the sequence or select a stage to inspect its role.
Prediction path
Visible patches
12 of 36 toy patches
Context encoder
Self-attention over visible patches
Predictor + target positions
Learned mask token + positional embeddings
Predicted features
One prediction per target block
T1
T2
T3
T4
Teacher target path
Full image
Includes every target region
Teacher encoder
Full-image features · no gradients
Normalize and select
Gather features at the target positions
Teacher features
Targets for the same four blocks
T1
T2
T3
T4
Feature loss
Compare predictions with teacher features at matching positions
After the optimizer step: update the teacher from the context encoder using EMA. Gradients update the context encoder and predictor, not the teacher.
Two paths, one feature objective
Both paths stay visible. The stage controls highlight how visible context becomes a prediction and how the teacher provides its learning target.
Implementation: paper, math, and Python
The same patch indices connect the original paper to the tensors and the executable code. Read each row from left to right, then continue to the next operation.
Follow one training step from masks to the teacher update. The Python excerpts come from one runnable program that uses the pinned official model classes. Its small CPU model and random inputs demonstrate the mechanics; the explorer below uses the released pretrained model on photographs.
1. Keep the actual visible and target indices
Original paper
A large context rectangle loses the regions covered by target blocks. The targets may overlap each other.
Math and tensor shapes
A patch is a row-major index. Keep those indices through every gather. The released sampler can relax exclusion after retries; this reference rejects overlapping context/target cases. Batch collation may also truncate the retained indices.
context: [B, Nc]; each target: [B, Nt]
Python implementation
def sample_masks(collator, images):
    """Retain actual indices; reject relaxed context-target overlap."""
    for _ in range(128):
        _, contexts, targets = collator(list(images))
        context = contexts[0].to(images.device)
        targets = [mask.to(images.device) for mask in targets]
        disjoint = all(
            not torch.isin(context[b], mask[b]).any()
            for mask in targets
            for b in range(len(images))
        )
        if disjoint:
            return context, targets  # Target blocks may overlap each other.
    raise ValueError("No disjoint context/target masks found in 128 attempts")
2. Encode only the visible patch tokens
Original paper
The context encoder processes the sparse visible patch sequence with a Vision Transformer.
Math and tensor shapes
The official encoder patchifies the image, adds fixed 2D sinusoidal positions, then gathers visible tokens before self-attention. Hidden pixels cannot enter that attention sequence. There is no CLS token.
visible features: [B, Nc, D]
Python implementation
def encode_context(encoder, images, context):
    """Official encoder: patchify + positions, gather, then self-attention."""
    return encoder(images, [context])  # [B, N_context, D], no CLS token.
3. Build teacher targets from the full image
Original paper
Paper excerpt · PDF p. 3
§3 Targets · Figure 3Targets are selected from the encoder output, after the teacher has processed the entire image.
Math and tensor shapes
The released loop adds feature-wise layer normalization before selecting each target block. The teacher sees every patch and its outputs are detached. It provides a learned feature target, not an RGB reconstruction.
full teacher: [B, N, D] → target i: [B, Nt, D]
Python implementation
@torch.no_grad()
def teacher_targets(teacher, images, targets):
    """Encode the full image before selecting target patch features."""
    full = teacher(images)
    full = F.layer_norm(full, (full.shape[-1],))
    return [gather_features(full, mask) for mask in targets]
4. Tell the predictor where to predict
Original paper
Paper excerpt · PDF p. 4
§3 PredictionEach positional query uses a shared learned mask token plus the position of a target patch.
Math and tensor shapes
The learned vector is shared across positions. Fixed positional embeddings distinguish the queries. A target patch contributes its position, never its hidden RGB values, to the predictor input.
queries for block i: [B, Nt, Dp]
Python implementation
def target_queries(predictor, indices):
    """One shared learned mask token plus each target's fixed 2D position."""
    positions = predictor.predictor_pos_embed.expand(len(indices), -1, -1)
    positions = gather_features(positions, indices)
    return predictor.mask_token + positions  # [B, N_target, D_predictor]
5. Predict each target block independently
Original paper
Paper excerpt · PDF p. 4
§3 Prediction · Figure 3The paper applies the predictor once per target block, conditioned on that block’s positions.
Math and tensor shapes
Project context features to the predictor width, add context positions, append one block’s queries, and run the transformer. Normalize at predictor width, select target tokens, then project back to encoder width. Preserve overlapping targets as separate block results.
real checkpoint: D = 1280; Dp = 384; output [B, Nt, 1280]
Python implementation
def predict_block(predictor, features, context, target):
    """The official predictor operations for one independent target block."""
    x = predictor.predictor_embed(features)
    positions = predictor.predictor_pos_embed.expand(len(x), -1, -1)
    x = x + gather_features(positions, context)
    n_context = x.shape[1]
    x = torch.cat((x, target_queries(predictor, target)), dim=1)
    for block in predictor.predictor_blocks:
        x = block(x)
    x = predictor.predictor_norm(x)[:, n_context:]
    return predictor.predictor_proj(x)  # [B, N_target, D]; do not normalize.


def predict_blocks(predictor, features, context, targets):
    """Preserve block IDs, including unequal sizes and overlapping patches."""
    return [
        predict_block(predictor, features, context, mask) for mask in targets
    ]
6. Optimize the context encoder and predictor
Original paper
The printed paper uses squared L2. The released training loop uses Smooth L1 instead.
Math and tensor shapes
Smooth L1 uses β = 1: half the squared residual below magnitude one, and absolute residual minus one-half otherwise. Average features and patches within each block, then blocks. For the released equal-sized blocks this matches its tensor-wide mean. Do not normalize predictions before loss.
each block: [B, Nt, D] → scalar loss; AdamW updates θ and φ
Python implementation
def prediction_loss(predictions, targets):
    """Mean Smooth L1 per block, then mean over blocks (released beta=1)."""
    if not predictions or len(predictions) != len(targets):
        raise ValueError("Expected matching nonempty prediction/target lists")
    if any(
        p.shape != h.shape for p, h in zip(predictions, targets, strict=True)
    ):
        raise ValueError("Prediction and target shapes must match")
    return torch.stack(
        [
            F.smooth_l1_loss(p, h, beta=1.0)
            for p, h in zip(predictions, targets, strict=True)
        ]
    ).mean()


def optimize(optimizer, predictions, targets):
    """Only the context encoder and predictor belong to this optimizer."""
    optimizer.zero_grad(set_to_none=True)
    loss = prediction_loss(predictions, targets)
    loss.backward()
    optimizer.step()
    return loss.detach()
7. Move the teacher toward the updated encoder
Original paper
Paper excerpt · PDF p. 4
§3 Loss · EMA updateThe target encoder follows an exponential moving average of the context encoder parameters.
Math and tensor shapes
Run the EMA after the optimizer step. The predictor is not copied into the teacher. The released recipe increases momentum linearly from 0.996 toward 1.0; the CPU example shortens that schedule to two steps.
teacher and context encoder have matching parameter shapes
Python implementation
@torch.no_grad()
def update_teacher(encoder, teacher, momentum):
    """Call after AdamW: the teacher follows the encoder, not the predictor."""
    if not 0 <= momentum <= 1:
        raise ValueError("Momentum must be between zero and one")
    for student, target in zip(
        encoder.parameters(), teacher.parameters(), strict=True
    ):
        target.mul_(momentum).add_(student, alpha=1 - momentum)
Inspect real pretrained predictions
Now replace the small random model with the released ViT-H/14, 300-epoch checkpoint. Choose a photograph, a saved mask, and a target block. The predictor’s feature error and a visible-context baseline share one scale across every example. These are offline measurements from the real checkpoint, not animated or generated feature values.
Measured pretrained predictions
What can the visible context predict?
ViT-H/14 predicts the teacher’s features at withheld positions. Compare its error with an average-visible-context baseline. These saved results measure feature agreement, not object recognition or confidence.
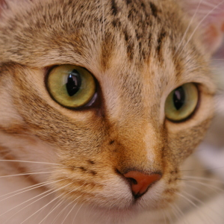
Teal outlines mark the selected target block. Dark patches are hidden from the context encoder. Other target blocks can overlap this one; each keeps its own predictions.
Patch 9 · row 0, column 9
- Predictor
- 0.0837
- Context mean
- 0.2978
- Shifted-target control
- 0.4320
Click a colored patch or use arrow keys within a heatmap; Home and End select its first and last patch. Error is Smooth L1 (β = 1), averaged over 1280 feature coordinates. Gray cells are outside this target block.
How these results were measured
All three model sections loaded strictly from the official 300-epoch checkpoint. RGB inputs use a center square crop, bicubic resize to 224, and ImageNet normalization. This deterministic diagnostic crop differs from the random training crop.
The baseline layer-normalizes each visible context feature, averages those features, and repeats the mean at every target position. It never sees full-image teacher features. The shifted-target control cyclically shifts teacher features within the selected block; it checks alignment and is not a semantic test.
For every case, changing all hidden tensor pixels left context features and predictions exactly unchanged. Teacher features changed. Heatmaps share one color scale; individual patches retain their raw errors.
Chelsea the cat: Stefan van der Walt · CC0. Image attribution.
Download measured results and provenance · Official checkpoint (10.36 GB)
Run the examples
Download the CPU training reference, the offline exporter, and the pinned requirements into the same directory. Python 3.13 was used to verify them. The model definitions and mask sampler come from an unchanged official checkout:
python3 -m venv .venv
source .venv/bin/activate
python -m pip install -r requirements-ijepa.txt
git clone https://github.com/facebookresearch/ijepa.git ijepa-official
git -C ijepa-official checkout 52c1ae95d05f743e000e8f10a1f3a79b10cff048
python ijepa_training.py --repo ijepa-official --steps 2
The reference uses two random 64×64 inputs and a two-layer encoder/predictor. It checks the forward path, loss, optimizer, and EMA; it does not train ImageNet representations. The downloadable source is the source of the highlighted excerpts above.
The real-model exporter needs the published 10.36 GB training checkpoint archive and substantially more memory. The saved cases were measured in float32 on an RTX A6000. To reproduce them, download the archive and run:
curl -L --fail -o IN1K-vit.h.14-300e.pth.tar \
  https://dl.fbaipublicfiles.com/ijepa/IN1K-vit.h.14-300e.pth.tar
CUBLAS_WORKSPACE_CONFIG=:4096:8 python ijepa_export.py \
  --repo ijepa-official --checkpoint IN1K-vit.h.14-300e.pth.tar \
  --root . --device cuda
The exporter saves lossless 224×224 crops and a prediction manifest containing actual indices, per-patch errors, checkpoint/source digests, package versions, and image credits. It also changes hidden pixels after preprocessing and verifies that context features and predictions remain unchanged. The site serves those small saved artifacts; readers do not need to load a model to explore them.
Semantic vs Texture Features
Feature prediction and pixel reconstruction place different demands on a model, but attention maps alone cannot explain a benchmark difference. The comparison below places handcrafted spatial weights over one photograph. It illustrates a distinction between center-focused and boundary-focused patterns; it is not a measured I-JEPA-versus-MAE experiment.
The measured explorer above answers a narrower question: how closely do predictions from visible context match the teacher’s hidden-position features? Low error is feature agreement, not proof that the model recognized an object. The paper’s generative predictor visualizations use an additional trained stochastic decoder; feature-error heatmaps do not reconstruct an image.
Illustrated Attention Patterns
Compare two handcrafted spatial patterns over the same photograph. The weights illustrate a visual distinction; neither map is measured I-JEPA or MAE attention.
Set to 0% to inspect the photograph without the overlays.
Center-focused pattern
Larger weights are assigned to a central patch region.
Handcrafted illustration · 8 × 8 patches
Boundary-focused pattern
Larger weights are assigned around chosen patch boundaries.
Handcrafted illustration · 8 × 8 patches
Label Efficiency
Table 2 evaluates pretrained models using 1% of ImageNet labels. For ViT-H/14 at 224 resolution, I-JEPA reaches 73.3%, compared with 71.5% for MAE ViT-H/14. The gap is 1.8 percentage points. The larger-resolution I-JEPA ViT-H/16 at 448 reaches 77.3%, but that is a different patch size and input resolution.
Each method uses whichever adaptation works best, fine-tuning or linear probing. Pretraining epochs and architectures also vary across methods. These results support label-efficient representations under the reported protocols; they do not establish a fixed reduction in annotation cost for another dataset. The chart below presents reported 1% results rather than invented 10% or 100% curves.
Published ImageNet results with 1% labels
Select an I-JEPA architecture. Table 2 uses each method’s best fine-tuning or linear-probing protocol.
Reported gap: 1.8 percentage points. Pretraining epochs differ, and these are published evaluations, not results from this page’s examples. Source: Table 2.
How I-JEPA Compares
Prediction objectives and reported evaluations
All listed numerical entries use 224 resolution. B, L, and H denote ViT sizes; the suffix is patch size. Architectures and pretraining epochs vary, and the two accuracy columns use different adaptation protocols.
| Method | Objective | View processing | Full-label linear | 1% labels |
|---|---|---|---|---|
| I-JEPA | Masked feature prediction | Single crop | 79.3% · H/14 | 73.3% · H/14 |
| MAE | Pixel reconstruction | Crop and flip | 77.2% · H/14 | 71.5% · H/14 |
| DINO | View self-distillation | Multi-crop and color transforms | 80.1% · B/8 | 70.0% · B/8 |
| data2vec | Masked feature prediction | Crop and masking | 77.3% · L/16 | 73.3% · L/16 |
| iBOT | View and patch self-distillation | Multi-crop and masking | 81.0% · L/16 | 69.7% · B/16 |
| Supervised | Label prediction | Recipe dependent | Not in Table 1 | Not in Table 2 |
Full-label linear evaluation freezes the encoder; 1% evaluation chooses fine-tuning or linear probing per method. iBOT’s two entries use different backbones. Source: final paper, Tables 1–2.
Key Results
| Method | Backbone / resolution | Full-label linear evaluation | 1% labels |
|---|---|---|---|
| I-JEPA | ViT-L/16 · 224 | 77.5% | 69.4% |
| I-JEPA | ViT-H/14 · 224 | 79.3% | 73.3% |
| I-JEPA | ViT-H/16 · 448 | 81.1% | 77.3% |
| MAE | ViT-H/14 · 224 | 77.2% | 71.5% |
| DINO | ViT-B/8 · 224 | 80.1% | 70.0% |
| data2vec | ViT-L/16 · 224 | 77.3% | 73.3% |
Source: final CVPR paper, Tables 1 and 2. The columns use different adaptation protocols. Full-label linear evaluation freezes the encoder. The 1% column reports each method’s best fine-tuning or linear-probing approach. These are published results, not measurements from the small examples on this page.
Why I-JEPA Matters
I-JEPA demonstrates a practical alternative to reconstructing pixels or matching extensively augmented views: predict missing information in a learned representation space. Its masking strategy, positional queries, and slowly updated target encoder make that idea concrete. The representation quality is evaluated through downstream tasks, rather than assumed from the objective.
The useful lesson is the separation of roles. Visible context supplies the predictor’s information. The full-image teacher supplies the learning target. A downstream task determines whether the learned encoder is useful. This separation also makes the method inspectable: we can track indices, rule out hidden-pixel leakage, and compare feature errors without pretending that a heatmap is a semantic explanation.
Key Takeaways
- The prediction target is a learned feature. Training does not require an RGB reconstruction decoder.
- Mask indices are part of the computation. Target blocks can overlap, while visible-context exclusion and retained batch indices need separate checks.
- The paper and released loss differ. The paper prints squared L2; the released training code uses mean Smooth L1.
- The teacher follows the encoder. Gradients train the context encoder and predictor; a linear momentum schedule controls the teacher’s EMA update.
- Measured predictions and downstream results answer different questions. Feature agreement is observable in the explorer; representation usefulness comes from the reported evaluation protocols.
Related Reading
- MAE — Masked autoencoders that reconstruct pixels
- V-JEPA — Extension of joint-embedding prediction to video
- DINO — Self-distillation with Vision Transformers and augmented views
- BEiT — BERT-style pre-training for images using discrete visual tokens
- BYOL — Non-contrastive learning with a predictor and EMA target
- SimCLR — Contrastive learning with augmented image views
- MoCo — Momentum contrast with a queue of negatives