
TL;DR
- BEiT trains a Vision Transformer to predict frozen DALL-E dVAE categories at masked patch positions, rather than reconstructing RGB pixels.
- Aligned views supply complete-image tokenizer targets and masked Transformer inputs; the encoder retains all patch positions, and only masked positions contribute to the loss.
- Visual code IDs are learned categories, not object labels, and token prediction alone does not guarantee semantic understanding.
- Original BEiT, later BEiT variants, and MAE report different training and evaluation recipes; their scores do not isolate the effect of target choice.
Paper Overview
BEiT, BERT Pre-Training of Image Transformers, adapts masked categorical prediction to vision. Published at ICLR 2022 by Hangbo Bao, Li Dong, Songhao Piao, and Furu Wei, it uses a frozen discrete variational autoencoder (dVAE) to tokenize images into a vocabulary of 8192 categories. A Vision Transformer learns to predict the labels at masked patch positions from visible context. Earlier work, including iGPT and ViT's masked-patch experiment, already explored prediction-based visual pretraining; BEiT's contribution is its particular discrete-target framework and its strong downstream results.
The tokenizer separates the target representation from the Transformer input. It compresses the complete image into learned categorical labels while BEiT sees selected patch embeddings replaced by a mask vector. This changes the learning objective from RGB regression to classification over visual codes. It does not guarantee semantic understanding, and the code IDs are not object labels.
Original paper Table 1 reports 83.2% ImageNet-1K top-one for BEiT-B/16 at 224px after 800 epochs of pretraining and downstream fine-tuning, compared with 81.8% for supervised DeiT-B in that table. BEiT-L reaches 85.2% at 224px. Table 3 reports base-model ADE20K single-scale SETR-PUP results of 45.6 mIoU, or 47.7 with intermediate ImageNet-1K fine-tuning. Appendix D's 56.7% base linear probe uses average patch features from the best middle layer, not simply the final special token.
The Visual Tokenizer
The main experiments reuse OpenAI's publicly released pretrained DALL-E dVAE. Training a tokenizer on ImageNet-1K is an Appendix C comparison, not the default recipe. The convolutional encoder receives a complete 112px image crop and outputs a 14×14 grid with 8192 categorical logits at each position. Its most likely category supplies the target:
This is vocabulary-axis argmax, not a nearest-codebook-vector lookup. The 112px tokenizer view and 224px Transformer view share one crop and flip, so their grids align. The encoder downsamples by eight, while BEiT uses 16px patches. Its convolutions give each target spatial context; the tokenizer does not independently label a collection of isolated 16px crops.
Only the encoder supplies BEiT's labels. The decoder belongs to the dVAE training objective and is not used for the masked-token results here. An integer category has no guaranteed name such as “sky” or “fur,” and numerical distance between two IDs has no similarity meaning. Later BEiT-2 explores a different target-learning approach, but its downstream gains also involve training and model choices.
Blockwise Masking Strategy
BEiT selects contiguous rectangles on the 14×14 patch grid. Paper Algorithm 1 describes minimum block area 16 and approximately 40% masking; the released sampler defaults to area 4. It samples area uniformly and aspect ratio uniformly in log space between 0.3 and 1/0.3, counting only newly masked positions when blocks overlap.
The requested count is 75 out of 196 patches, or 38.3%. Bounded retries can leave fewer selected patches: the real examples below contain 75 and 74. The executable implementation preserves that behavior instead of filling the remainder with random individual patches.
Contiguous masking removes nearby visual context over larger regions. It changes the geometry of the prediction task relative to scattered masking, but this alone does not establish semantic reasoning or explain cross-method accuracy differences. BEiT keeps every patch position in the encoder; MAE instead encodes only its visible patches. The following 8×8 demo is a geometric illustration, not the actual 14×14 sampler or a measurement of representation quality.
The BEiT Pipeline
Two aligned views play different roles. The complete 112px view reaches the frozen tokenizer and produces 196 integer targets. The 224px view reaches the Transformer, where selected patch embeddings are replaced with a shared learned mask vector. The model retains all 196 patch positions and prepends one special token, making the full encoder sequence length 197.
The encoder's self-attention lets masked and visible positions exchange context. Its attention matrix covers 197×197 positions regardless of the patch mask. MAE's visible-only encoder has a smaller matrix, although the resulting whole-model speed difference also depends on its decoder and implementation.
After encoding, BEiT excludes the special token from its vocabulary head and predicts 8192-category logits at each patch position. Only selected positions contribute to cross entropy. The schematic below shows invented token outputs; actual learned predictions appear after the implementation.
Token Prediction vs Pixel Reconstruction
BEiT predicts learned visual-token categories with cross entropy, while MAE reconstructs per-patch normalized pixels with mean squared error. For selected patch positions \mathcal{M}, the executable mean loss is:
The original paper writes a summed log-likelihood objective. Averaging selected positions gives the release's training reduction. Cross entropy trains a distribution over categories and can represent uncertainty; it does not force a semantic commitment. Displaying the argmax category is a separate readout. MSE and categorical prediction make different target and distributional assumptions, rather than providing a general ranking of semantic quality.
Published base-model results are close after fine-tuning: BEiT 83.2% and MAE 83.6%. Their reported linear probes, 56.7% and 68.0%, use different protocols. In particular, BEiT reports the best middle-layer average patch representation. These numbers do not isolate the cause of a feature difference or establish that one objective requires nonlinear adaptation. The next section makes the target, mask and measured outputs concrete.
Implementation
The frozen DALL-E encoder supplies labels from the complete 112px crop. BEiT receives the aligned 224px crop with selected patch embeddings replaced by its mask vector. Follow those two roles through the exact executed Python below.
1. Make two views of one crop
Original paper
One image supplies both patch embeddings and visual-token labels. The released transforms use different resolutions for these two branches.
Math and tensor shapes
Crop and flip once, then resize into aligned 14 × 14 grids. Normalize the bicubic 224px view with ImageNet mean and standard deviation. Map the Lanczos 112px view into [0.1, 0.9] for DALL-E. The tokenizer sees the complete crop, including regions that BEiT will not see. These photo examples use a deterministic center-square crop and no flip; they do not recreate the full training augmentation policy.
BEiT: [B, 3, 224, 224]; dVAE: [B, 3, 112, 112]
Python implementation
def make_views(image, crop_box=None, flip=False):
    """Crop once, then make spatially aligned Transformer and tokenizer views."""
    crop = _crop(image, crop_box)
    if flip:
        crop = crop.transpose(Image.Transpose.FLIP_LEFT_RIGHT)
    beit_crop = crop.resize((224, 224), Image.Resampling.BICUBIC)
    dvae_crop = crop.resize((112, 112), Image.Resampling.LANCZOS)
    mean = torch.tensor(IMAGENET_MEAN).reshape(3, 1, 1)
    std = torch.tensor(IMAGENET_STD).reshape(3, 1, 1)
    return {
        "beit": (_pixels(beit_crop) - mean) / std,
        "dvae": 0.8 * _pixels(dvae_crop) + 0.1,
        "beit_crop": beit_crop,
        "dvae_crop": dvae_crop,
    }
2. Ask the frozen tokenizer for categorical targets
Original paper
The original experiments reuse the pretrained DALL-E discrete VAE. Its encoder is fixed while BEiT learns the masked-image prior.
Math and tensor shapes
Take argmax across the vocabulary axis, then flatten rows before columns. This is categorical prediction, not a nearest-vector lookup. The convolutional tokenizer has spatial context across the crop; each integer identifies an arbitrary learned category, not a named object. Evaluation mode, frozen parameters, and no_grad keep targets outside the student gradient graph.
[B, 8192, 14, 14] → [B, 196] integer labels
Python implementation
def visual_targets(tokenizer, dvae_images):
    """Freeze the tokenizer and flatten vocabulary argmax in row-major order."""
    images = _image_batch(dvae_images)
    if images.shape[2] % 8 or images.shape[3] % 8:
        raise ValueError("DALL-E view dimensions must be divisible by eight")
    tokenizer.eval().requires_grad_(False)
    for parameter in tokenizer.parameters():
        parameter.grad = None
    with torch.no_grad():
        logits = tokenizer(images)
        _validate_tokenizer_logits(logits, images)
        return logits.argmax(dim=1).flatten(1)
3. Select rectangles and retain their actual count
Original paper
Paper excerpt · PDF p. 4
Algorithm 1 · released mask samplerThe paper describes minimum block area 16. The released default is 4, with at most 75 selected patch positions.
Math and tensor shapes
Sample area uniformly and aspect ratio uniformly in log space between 0.3 and 1/0.3. Count only newly selected cells in overlapping rectangles. The helper bounds attempts and stops when a rectangle cannot be added; it never silently fills the remainder with random patches. Seeds 0 and 4 below produce 75 and 74 selections. Use the actual count as the loss and agreement denominator.
m: Boolean [B, 196]; special token excluded
Python implementation
def block_mask(grid_size=14, num_masked=75, seed=0, min_area=4):
    """Released rectangle algorithm; bounded retries can leave an undershoot."""
    height, width = _grid(grid_size)
    _integer(num_masked, "num_masked", minimum=0)
    _integer(min_area, "min_area")
    if num_masked > height * width:
        raise ValueError("num_masked cannot exceed the patch grid")
    rng = random.Random(seed)
    mask = torch.zeros(height, width, dtype=torch.bool)
    count = 0
    while count < num_masked:
        added = _place_rectangle(mask, num_masked - count, min_area, rng)
        if added == 0:
            break  # No random single-patch completion.
        count += added
    return mask.flatten()
4. Replace embeddings, then prepend the special token
Original paper
Selected patches carry a shared learned mask embedding. They stay in the encoder rather than being removed.
Math and tensor shapes
Project non-overlapping 16px patches, replace selected embeddings, and prepend one special token. Only the 196 patch positions have mask indices or visual-token targets. The original MIM checkpoint adds absolute position vectors to all 197 slots. The later classifier uses relative position bias instead.
[B, 196, 768] → [B, 197, 768]
Python implementation
def embed(self, images, mask=None):
    """Replace selected patch embeddings, then add the special token/positions."""
    patches = self.patch_embed(images)
    batch, count, _ = patches.shape
    if mask is not None:
        if self.profile != "mim":
            raise ValueError(
                "classification uses every patch and accepts no mask"
            )
        mask = _patch_mask(mask, batch, count, patches.device)
        patches = torch.where(mask.unsqueeze(-1), self.mask_token, patches)
    sequence = torch.cat(
        (self.cls_token.expand(batch, -1, -1), patches), dim=1
    )
    return sequence if self.pos_embed is None else sequence + self.pos_embed
5. Let all 197 positions exchange context
Original paper
Paper excerpt · PDF p. 3
§2.2 · §2.5 · released encoderThe original base model has twelve pre-norm blocks, width 768 and twelve attention heads. Released classifier extensions are explicit in the code.
Math and tensor shapes
Attention mixes positions; the 768 → 3072 → 768 GELU MLP mixes channels at each position. For the original 1K MIM profile, R is absent and LayerScale is absent. The later 22K classifier adds relative bias R and learned branch scales. Dropout and stochastic depth are disabled at evaluation. These extensions belong to the release, not to the original paper equations.
Q, K, V: [B, 12, 197, 64]; attention: [B, 12, 197, 197]
Python implementation
def scaled_attention(q, k, v, scale, relative_bias=None):
    """Each query attends to the entire retained sequence, including masked slots."""
    scores = (q * scale) @ k.transpose(-2, -1)
    if relative_bias is not None:
        scores = scores + relative_bias  # Released classification extension.
    return scores.softmax(dim=-1) @ v


def encode_block(sequence, block):
    """Pre-norm residuals; the classifier release adds learned LayerScale."""
    attention = block.attn(block.norm1(sequence))
    if block.gamma_1 is not None:
        attention = block.gamma_1 * attention
    sequence = sequence + block._drop(attention)
    mlp = block.mlp(block.norm2(sequence))
    if block.gamma_2 is not None:
        mlp = block.gamma_2 * mlp
    return sequence + block._drop(mlp)


def encode_sequence(sequence, blocks, final_norm):
    """All 196 patch slots plus the special token remain throughout the encoder."""
    for block in blocks:
        sequence = block(sequence)
    return final_norm(sequence)  # Identity for the mean-pooling classifier.
6. Score only selected patch predictions
Original paper
The paper maximizes a summed log likelihood over masked positions. The executable training loss averages their negative log likelihood.
Math and tensor shapes
The vocabulary head follows the final encoder normalization and excludes the special token. Select logits and integer labels with the same Boolean mask. Cross entropy accepts raw logits and computes log-softmax internally. Visible predictions are unscored, and an empty mask is rejected. A distribution can express uncertainty across categories; argmax is only the displayed top-one choice.
[B, 196, 8192] → [M, 8192] → scalar loss
Python implementation
def masked_loss(logits, targets, mask):
    """Average raw-logit cross entropy only over selected patch positions."""
    if logits.ndim != 3 or logits.shape[-1] < 1:
        raise ValueError("logits must have shape [B,N,V]")
    if targets.shape != logits.shape[:2] or targets.dtype != torch.long:
        raise ValueError("targets must be integer [B,N] labels")
    mask = _patch_mask(mask, *logits.shape[:2], logits.device)
    if not mask.any():
        raise ValueError("masked loss requires at least one selected patch")
    return F.cross_entropy(logits[mask], targets.to(logits.device)[mask])
7. Update the student while its targets stay fixed
Original paper
Paper excerpt · PDF p. 5
§2.4–2.5 · two-stage trainingThe tokenizer supplies fixed targets. The original BEiT pretraining uses unlabeled ImageNet-1K images for 800 epochs.
Math and tensor shapes
Clear accumulated gradients, run the masked student, backpropagate the finite objective, and update. The patch projection, mask vector, encoder, and vocabulary head learn; the tokenizer does not. The downloadable smoke command uses two synthetic images and a tiny synthetic target provider to verify these mechanics. It does not train the paper model or reproduce its accuracy, schedule, or data pipeline.
Loss: scalar; gradients: BEiT parameters only
Python implementation
def training_step(model, tokenizer, views, mask, optimizer):
    """Update BEiT only; the tokenizer sees the complete aligned crop."""
    _student_optimizer(model, optimizer)
    targets = visual_targets(tokenizer, views["dvae"])
    model.train()
    optimizer.zero_grad(set_to_none=True)
    logits = model(_image_batch(views["beit"]), mask)
    loss = masked_loss(logits, targets, mask)
    if not torch.isfinite(loss):
        raise ValueError(
            "masked loss must be finite before updating parameters"
        )
    loss.backward()
    optimizer.step()
    return loss.item()
8. Replace the objective with an image-class readout
Original paper
Paper excerpt · PDF p. 5
§2.6 · released mean-pooling classifierFine-tuning uses labeled images and a class head. The displayed classifier is a separate released 22K-to-1K checkpoint.
Math and tensor shapes
Keep all image patches visible. Exclude the special token, average patch features, apply fc_norm, and use the 1,000-class head. This checkpoint expects a bicubic shorter-edge resize to 256, center crop to 224, and mean/std 0.5. Softmax is for displaying class probabilities; neither this readout nor its preprocessing is the MIM path.
[B, 197, 768] → [B, 768] → [B, 1000]
Python implementation
def classification_readout(encoded, pooling_norm, classifier):
    """Released readout: exclude special token, mean patches, normalize, classify."""
    patch_features = encoded[:, 1:]
    image_features = pooling_norm(patch_features.mean(dim=1))
    return classifier(image_features)
Keep these files together. CPU wheels are sufficient; real inference downloads and verifies the weights once, then caches them.
beit.pybeit_tokenizer.pybeit_export.pyrequirements-beit.txtbeit-NOTICE.txt
python -m pip install -r requirements-beit.txt
python beit.py --smoke
python beit.py --mim --image photo.png --seed 0 --output-dir mim
python beit.py --predict --image photo.png --output-dir classification
python beit_export.py --output-dir beit-demo --cache-dir ~/.cache/beit-example
Smoke checks mechanics with synthetic targets. The following photo outputs use learned checkpoints. The excerpts and syntax tokens are generated from the downloadable source.
Real masked-token predictions
The following CPU float32 outputs use beit_base_patch16_224_pt1k_800ep.pth: ImageNet-1K masked image modeling, 800 epochs, absolute positions, no relative bias or LayerScale. Frozen encoder.pkl supplies learned DALL-E labels. These two image/mask cases measure category agreement, not classification accuracy, segmentation, or image reconstruction.
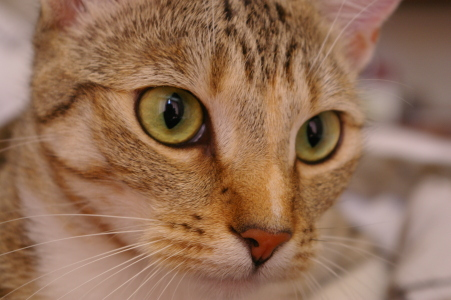
Chelsea the cat
Seed 0 · Requested 75 · Actual masked 75/196 · Matches 1/75 (1.33%) · Mean cross entropy 6.407495
Teal outlines mark selected targets. Predicted cells: teal = same category, amber = different category, dash = visible and unscored. Colors indicate mask/equality only; numerical distance between IDs has no similarity meaning.
Exact token IDs and mask state: Chelsea the cat
| Row, col | Mask | Target ID | Predicted ID | Agreement |
|---|---|---|---|---|
| 1, 1 | visible | 3782 | null (unscored) | unscored |
| 1, 2 | visible | 8045 | null (unscored) | unscored |
| 1, 3 | visible | 2346 | null (unscored) | unscored |
| 1, 4 | visible | 7934 | null (unscored) | unscored |
| 1, 5 | visible | 4406 | null (unscored) | unscored |
| 1, 6 | visible | 2152 | null (unscored) | unscored |
| 1, 7 | visible | 2389 | null (unscored) | unscored |
| 1, 8 | visible | 7164 | null (unscored) | unscored |
| 1, 9 | visible | 1414 | null (unscored) | unscored |
| 1, 10 | visible | 500 | null (unscored) | unscored |
| 1, 11 | visible | 2132 | null (unscored) | unscored |
| 1, 12 | visible | 5888 | null (unscored) | unscored |
| 1, 13 | visible | 7274 | null (unscored) | unscored |
| 1, 14 | visible | 6299 | null (unscored) | unscored |
| 2, 1 | visible | 2649 | null (unscored) | unscored |
| 2, 2 | visible | 1182 | null (unscored) | unscored |
| 2, 3 | visible | 3159 | null (unscored) | unscored |
| 2, 4 | visible | 2677 | null (unscored) | unscored |
| 2, 5 | visible | 1881 | null (unscored) | unscored |
| 2, 6 | visible | 1030 | null (unscored) | unscored |
| 2, 7 | visible | 1115 | null (unscored) | unscored |
| 2, 8 | visible | 5667 | null (unscored) | unscored |
| 2, 9 | visible | 4836 | null (unscored) | unscored |
| 2, 10 | visible | 8138 | null (unscored) | unscored |
| 2, 11 | visible | 797 | null (unscored) | unscored |
| 2, 12 | visible | 2925 | null (unscored) | unscored |
| 2, 13 | visible | 7657 | null (unscored) | unscored |
| 2, 14 | visible | 2149 | null (unscored) | unscored |
| 3, 1 | visible | 2933 | null (unscored) | unscored |
| 3, 2 | visible | 5167 | null (unscored) | unscored |
| 3, 3 | visible | 3360 | null (unscored) | unscored |
| 3, 4 | visible | 3153 | null (unscored) | unscored |
| 3, 5 | visible | 1978 | null (unscored) | unscored |
| 3, 6 | visible | 6088 | null (unscored) | unscored |
| 3, 7 | visible | 7378 | null (unscored) | unscored |
| 3, 8 | visible | 256 | null (unscored) | unscored |
| 3, 9 | visible | 4229 | null (unscored) | unscored |
| 3, 10 | visible | 5146 | null (unscored) | unscored |
| 3, 11 | visible | 827 | null (unscored) | unscored |
| 3, 12 | visible | 1094 | null (unscored) | unscored |
| 3, 13 | visible | 4424 | null (unscored) | unscored |
| 3, 14 | visible | 3140 | null (unscored) | unscored |
| 4, 1 | masked | 1913 | 4990 | different |
| 4, 2 | masked | 2156 | 712 | different |
| 4, 3 | masked | 6648 | 6920 | different |
| 4, 4 | masked | 7174 | 1654 | different |
| 4, 5 | masked | 5970 | 6064 | different |
| 4, 6 | masked | 5490 | 6063 | different |
| 4, 7 | visible | 3777 | null (unscored) | unscored |
| 4, 8 | visible | 888 | null (unscored) | unscored |
| 4, 9 | visible | 3021 | null (unscored) | unscored |
| 4, 10 | visible | 6499 | null (unscored) | unscored |
| 4, 11 | visible | 658 | null (unscored) | unscored |
| 4, 12 | visible | 902 | null (unscored) | unscored |
| 4, 13 | visible | 2726 | null (unscored) | unscored |
| 4, 14 | visible | 4079 | null (unscored) | unscored |
| 5, 1 | masked | 5024 | 2947 | different |
| 5, 2 | masked | 4623 | 4716 | different |
| 5, 3 | masked | 847 | 4415 | different |
| 5, 4 | masked | 6674 | 5193 | different |
| 5, 5 | masked | 5077 | 3816 | different |
| 5, 6 | masked | 3892 | 6532 | different |
| 5, 7 | visible | 2927 | null (unscored) | unscored |
| 5, 8 | visible | 5515 | null (unscored) | unscored |
| 5, 9 | visible | 259 | null (unscored) | unscored |
| 5, 10 | visible | 4601 | null (unscored) | unscored |
| 5, 11 | visible | 8173 | null (unscored) | unscored |
| 5, 12 | visible | 7250 | null (unscored) | unscored |
| 5, 13 | visible | 5871 | null (unscored) | unscored |
| 5, 14 | visible | 7206 | null (unscored) | unscored |
| 6, 1 | masked | 1300 | 4707 | different |
| 6, 2 | masked | 2530 | 120 | different |
| 6, 3 | masked | 5426 | 3231 | different |
| 6, 4 | masked | 5434 | 8113 | different |
| 6, 5 | masked | 3585 | 1281 | different |
| 6, 6 | masked | 978 | 7413 | different |
| 6, 7 | visible | 1755 | null (unscored) | unscored |
| 6, 8 | visible | 3580 | null (unscored) | unscored |
| 6, 9 | visible | 3043 | null (unscored) | unscored |
| 6, 10 | masked | 5590 | 4228 | different |
| 6, 11 | visible | 1104 | null (unscored) | unscored |
| 6, 12 | visible | 3747 | null (unscored) | unscored |
| 6, 13 | visible | 5172 | null (unscored) | unscored |
| 6, 14 | visible | 6408 | null (unscored) | unscored |
| 7, 1 | masked | 5348 | 5263 | different |
| 7, 2 | masked | 7227 | 7281 | different |
| 7, 3 | masked | 5174 | 2922 | different |
| 7, 4 | masked | 6514 | 4518 | different |
| 7, 5 | masked | 5022 | 5546 | different |
| 7, 6 | masked | 4935 | 1957 | different |
| 7, 7 | visible | 5988 | null (unscored) | unscored |
| 7, 8 | visible | 8119 | null (unscored) | unscored |
| 7, 9 | visible | 520 | null (unscored) | unscored |
| 7, 10 | masked | 5760 | 2235 | different |
| 7, 11 | visible | 396 | null (unscored) | unscored |
| 7, 12 | visible | 4480 | null (unscored) | unscored |
| 7, 13 | masked | 3946 | 3946 | match |
| 7, 14 | masked | 7935 | 5103 | different |
| 8, 1 | masked | 3149 | 810 | different |
| 8, 2 | masked | 7895 | 7737 | different |
| 8, 3 | masked | 6733 | 7664 | different |
| 8, 4 | masked | 1554 | 7243 | different |
| 8, 5 | masked | 2168 | 5624 | different |
| 8, 6 | masked | 6825 | 7766 | different |
| 8, 7 | visible | 2402 | null (unscored) | unscored |
| 8, 8 | visible | 7157 | null (unscored) | unscored |
| 8, 9 | visible | 6903 | null (unscored) | unscored |
| 8, 10 | masked | 6304 | 6146 | different |
| 8, 11 | visible | 5145 | null (unscored) | unscored |
| 8, 12 | visible | 204 | null (unscored) | unscored |
| 8, 13 | masked | 2582 | 8084 | different |
| 8, 14 | masked | 3144 | 4418 | different |
| 9, 1 | masked | 2552 | 5364 | different |
| 9, 2 | masked | 6295 | 8103 | different |
| 9, 3 | masked | 3997 | 6864 | different |
| 9, 4 | masked | 5099 | 1799 | different |
| 9, 5 | masked | 1778 | 142 | different |
| 9, 6 | masked | 2460 | 1536 | different |
| 9, 7 | visible | 4525 | null (unscored) | unscored |
| 9, 8 | visible | 373 | null (unscored) | unscored |
| 9, 9 | visible | 1882 | null (unscored) | unscored |
| 9, 10 | masked | 4897 | 2729 | different |
| 9, 11 | visible | 6914 | null (unscored) | unscored |
| 9, 12 | visible | 3624 | null (unscored) | unscored |
| 9, 13 | visible | 4729 | null (unscored) | unscored |
| 9, 14 | visible | 7369 | null (unscored) | unscored |
| 10, 1 | masked | 3997 | 369 | different |
| 10, 2 | masked | 5765 | 3045 | different |
| 10, 3 | masked | 3388 | 5515 | different |
| 10, 4 | masked | 8010 | 278 | different |
| 10, 5 | masked | 5923 | 8067 | different |
| 10, 6 | masked | 4424 | 5970 | different |
| 10, 7 | visible | 7256 | null (unscored) | unscored |
| 10, 8 | visible | 2868 | null (unscored) | unscored |
| 10, 9 | visible | 477 | null (unscored) | unscored |
| 10, 10 | visible | 8145 | null (unscored) | unscored |
| 10, 11 | visible | 7389 | null (unscored) | unscored |
| 10, 12 | visible | 5625 | null (unscored) | unscored |
| 10, 13 | visible | 6624 | null (unscored) | unscored |
| 10, 14 | visible | 8142 | null (unscored) | unscored |
| 11, 1 | masked | 2124 | 5515 | different |
| 11, 2 | masked | 7799 | 6299 | different |
| 11, 3 | masked | 7557 | 826 | different |
| 11, 4 | masked | 4486 | 3384 | different |
| 11, 5 | masked | 597 | 3086 | different |
| 11, 6 | masked | 5821 | 3809 | different |
| 11, 7 | visible | 1667 | null (unscored) | unscored |
| 11, 8 | visible | 276 | null (unscored) | unscored |
| 11, 9 | visible | 6201 | null (unscored) | unscored |
| 11, 10 | visible | 2145 | null (unscored) | unscored |
| 11, 11 | visible | 1424 | null (unscored) | unscored |
| 11, 12 | visible | 5897 | null (unscored) | unscored |
| 11, 13 | visible | 4397 | null (unscored) | unscored |
| 11, 14 | visible | 2197 | null (unscored) | unscored |
| 12, 1 | masked | 6764 | 6299 | different |
| 12, 2 | masked | 335 | 449 | different |
| 12, 3 | masked | 2232 | 923 | different |
| 12, 4 | masked | 3118 | 3857 | different |
| 12, 5 | masked | 4639 | 7517 | different |
| 12, 6 | masked | 5952 | 1130 | different |
| 12, 7 | visible | 2053 | null (unscored) | unscored |
| 12, 8 | visible | 311 | null (unscored) | unscored |
| 12, 9 | visible | 979 | null (unscored) | unscored |
| 12, 10 | visible | 5833 | null (unscored) | unscored |
| 12, 11 | visible | 3669 | null (unscored) | unscored |
| 12, 12 | visible | 5159 | null (unscored) | unscored |
| 12, 13 | visible | 6922 | null (unscored) | unscored |
| 12, 14 | visible | 6005 | null (unscored) | unscored |
| 13, 1 | masked | 3488 | 6802 | different |
| 13, 2 | masked | 4344 | 6296 | different |
| 13, 3 | masked | 1707 | 449 | different |
| 13, 4 | masked | 5487 | 449 | different |
| 13, 5 | masked | 5149 | 1799 | different |
| 13, 6 | masked | 2525 | 7585 | different |
| 13, 7 | masked | 1183 | 2341 | different |
| 13, 8 | visible | 5383 | null (unscored) | unscored |
| 13, 9 | visible | 1280 | null (unscored) | unscored |
| 13, 10 | visible | 3063 | null (unscored) | unscored |
| 13, 11 | visible | 7243 | null (unscored) | unscored |
| 13, 12 | visible | 8129 | null (unscored) | unscored |
| 13, 13 | visible | 4852 | null (unscored) | unscored |
| 13, 14 | visible | 3233 | null (unscored) | unscored |
| 14, 1 | masked | 6627 | 6802 | different |
| 14, 2 | masked | 7775 | 6804 | different |
| 14, 3 | masked | 2577 | 6804 | different |
| 14, 4 | masked | 4598 | 5192 | different |
| 14, 5 | masked | 1711 | 4589 | different |
| 14, 6 | masked | 4589 | 5192 | different |
| 14, 7 | visible | 4385 | null (unscored) | unscored |
| 14, 8 | visible | 3821 | null (unscored) | unscored |
| 14, 9 | visible | 5493 | null (unscored) | unscored |
| 14, 10 | visible | 3960 | null (unscored) | unscored |
| 14, 11 | visible | 5820 | null (unscored) | unscored |
| 14, 12 | visible | 7034 | null (unscored) | unscored |
| 14, 13 | visible | 5696 | null (unscored) | unscored |
| 14, 14 | visible | 2928 | null (unscored) | unscored |
Photo: Stefan van der Walt · Pinned source · CC0 · Original photograph

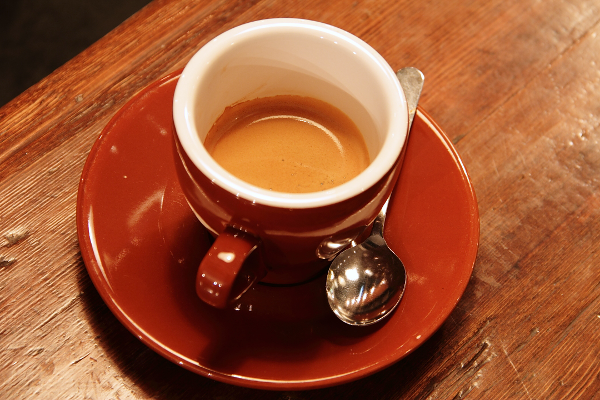
Cup of coffee
Seed 4 · Requested 75 · Actual masked 74/196 · Matches 7/74 (9.46%) · Mean cross entropy 4.745119
Teal outlines mark selected targets. Predicted cells: teal = same category, amber = different category, dash = visible and unscored. Colors indicate mask/equality only; numerical distance between IDs has no similarity meaning.
Exact token IDs and mask state: Cup of coffee
| Row, col | Mask | Target ID | Predicted ID | Agreement |
|---|---|---|---|---|
| 1, 1 | visible | 418 | null (unscored) | unscored |
| 1, 2 | visible | 272 | null (unscored) | unscored |
| 1, 3 | visible | 6907 | null (unscored) | unscored |
| 1, 4 | masked | 5957 | 386 | different |
| 1, 5 | masked | 5902 | 1356 | different |
| 1, 6 | masked | 4998 | 217 | different |
| 1, 7 | masked | 7023 | 5881 | different |
| 1, 8 | masked | 217 | 217 | match |
| 1, 9 | visible | 6667 | null (unscored) | unscored |
| 1, 10 | visible | 6636 | null (unscored) | unscored |
| 1, 11 | visible | 1228 | null (unscored) | unscored |
| 1, 12 | visible | 560 | null (unscored) | unscored |
| 1, 13 | visible | 6301 | null (unscored) | unscored |
| 1, 14 | visible | 6717 | null (unscored) | unscored |
| 2, 1 | visible | 2426 | null (unscored) | unscored |
| 2, 2 | visible | 760 | null (unscored) | unscored |
| 2, 3 | visible | 6580 | null (unscored) | unscored |
| 2, 4 | masked | 6724 | 3348 | different |
| 2, 5 | masked | 287 | 287 | match |
| 2, 6 | masked | 1058 | 6762 | different |
| 2, 7 | masked | 8125 | 6286 | different |
| 2, 8 | masked | 7043 | 4423 | different |
| 2, 9 | visible | 1405 | null (unscored) | unscored |
| 2, 10 | visible | 145 | null (unscored) | unscored |
| 2, 11 | visible | 3592 | null (unscored) | unscored |
| 2, 12 | visible | 6941 | null (unscored) | unscored |
| 2, 13 | visible | 3265 | null (unscored) | unscored |
| 2, 14 | visible | 6044 | null (unscored) | unscored |
| 3, 1 | visible | 2389 | null (unscored) | unscored |
| 3, 2 | visible | 6201 | null (unscored) | unscored |
| 3, 3 | visible | 4572 | null (unscored) | unscored |
| 3, 4 | masked | 6573 | 3097 | different |
| 3, 5 | masked | 5839 | 3493 | different |
| 3, 6 | masked | 2196 | 1339 | different |
| 3, 7 | masked | 3903 | 5054 | different |
| 3, 8 | masked | 8003 | 8003 | match |
| 3, 9 | visible | 1334 | null (unscored) | unscored |
| 3, 10 | visible | 701 | null (unscored) | unscored |
| 3, 11 | visible | 5106 | null (unscored) | unscored |
| 3, 12 | visible | 3627 | null (unscored) | unscored |
| 3, 13 | visible | 4911 | null (unscored) | unscored |
| 3, 14 | visible | 5647 | null (unscored) | unscored |
| 4, 1 | visible | 5829 | null (unscored) | unscored |
| 4, 2 | visible | 1131 | null (unscored) | unscored |
| 4, 3 | visible | 6566 | null (unscored) | unscored |
| 4, 4 | masked | 4451 | 223 | different |
| 4, 5 | masked | 4692 | 681 | different |
| 4, 6 | masked | 7776 | 7031 | different |
| 4, 7 | masked | 680 | 2586 | different |
| 4, 8 | masked | 3390 | 3390 | match |
| 4, 9 | visible | 1871 | null (unscored) | unscored |
| 4, 10 | visible | 3802 | null (unscored) | unscored |
| 4, 11 | visible | 5841 | null (unscored) | unscored |
| 4, 12 | visible | 6614 | null (unscored) | unscored |
| 4, 13 | visible | 6614 | null (unscored) | unscored |
| 4, 14 | visible | 7585 | null (unscored) | unscored |
| 5, 1 | visible | 2395 | null (unscored) | unscored |
| 5, 2 | visible | 4672 | null (unscored) | unscored |
| 5, 3 | visible | 7005 | null (unscored) | unscored |
| 5, 4 | masked | 1727 | 5416 | different |
| 5, 5 | masked | 7258 | 6262 | different |
| 5, 6 | masked | 3265 | 3325 | different |
| 5, 7 | masked | 7662 | 2457 | different |
| 5, 8 | masked | 3729 | 1551 | different |
| 5, 9 | visible | 5998 | null (unscored) | unscored |
| 5, 10 | visible | 6594 | null (unscored) | unscored |
| 5, 11 | visible | 2237 | null (unscored) | unscored |
| 5, 12 | visible | 111 | null (unscored) | unscored |
| 5, 13 | visible | 92 | null (unscored) | unscored |
| 5, 14 | visible | 793 | null (unscored) | unscored |
| 6, 1 | visible | 1662 | null (unscored) | unscored |
| 6, 2 | visible | 6667 | null (unscored) | unscored |
| 6, 3 | visible | 2507 | null (unscored) | unscored |
| 6, 4 | masked | 2964 | 5674 | different |
| 6, 5 | masked | 7417 | 7363 | different |
| 6, 6 | masked | 2823 | 1340 | different |
| 6, 7 | masked | 1340 | 1340 | match |
| 6, 8 | masked | 3286 | 4249 | different |
| 6, 9 | visible | 4454 | null (unscored) | unscored |
| 6, 10 | visible | 5995 | null (unscored) | unscored |
| 6, 11 | visible | 4276 | null (unscored) | unscored |
| 6, 12 | visible | 5977 | null (unscored) | unscored |
| 6, 13 | visible | 5856 | null (unscored) | unscored |
| 6, 14 | visible | 5263 | null (unscored) | unscored |
| 7, 1 | visible | 4672 | null (unscored) | unscored |
| 7, 2 | visible | 5584 | null (unscored) | unscored |
| 7, 3 | visible | 92 | null (unscored) | unscored |
| 7, 4 | masked | 374 | 686 | different |
| 7, 5 | masked | 8183 | 4682 | different |
| 7, 6 | masked | 1779 | 873 | different |
| 7, 7 | masked | 3789 | 7532 | different |
| 7, 8 | masked | 7366 | 1990 | different |
| 7, 9 | masked | 2528 | 2528 | match |
| 7, 10 | masked | 153 | 3780 | different |
| 7, 11 | masked | 4888 | 2856 | different |
| 7, 12 | masked | 5454 | 4866 | different |
| 7, 13 | masked | 2630 | 3862 | different |
| 7, 14 | masked | 7501 | 7232 | different |
| 8, 1 | visible | 2630 | null (unscored) | unscored |
| 8, 2 | visible | 7521 | null (unscored) | unscored |
| 8, 3 | visible | 4035 | null (unscored) | unscored |
| 8, 4 | masked | 2960 | 1607 | different |
| 8, 5 | masked | 2489 | 5892 | different |
| 8, 6 | masked | 5977 | 5720 | different |
| 8, 7 | masked | 8147 | 1305 | different |
| 8, 8 | masked | 8166 | 3130 | different |
| 8, 9 | masked | 3747 | 649 | different |
| 8, 10 | masked | 2600 | 536 | different |
| 8, 11 | masked | 386 | 8093 | different |
| 8, 12 | masked | 7192 | 2778 | different |
| 8, 13 | masked | 6948 | 6948 | match |
| 8, 14 | masked | 2460 | 1608 | different |
| 9, 1 | visible | 6915 | null (unscored) | unscored |
| 9, 2 | visible | 1527 | null (unscored) | unscored |
| 9, 3 | visible | 6544 | null (unscored) | unscored |
| 9, 4 | masked | 4233 | 5129 | different |
| 9, 5 | masked | 2277 | 5250 | different |
| 9, 6 | masked | 5999 | 2630 | different |
| 9, 7 | masked | 3291 | 5977 | different |
| 9, 8 | masked | 2354 | 1740 | different |
| 9, 9 | masked | 4621 | 491 | different |
| 9, 10 | masked | 3223 | 3947 | different |
| 9, 11 | masked | 1356 | 8089 | different |
| 9, 12 | masked | 6264 | 2778 | different |
| 9, 13 | masked | 1527 | 1435 | different |
| 9, 14 | masked | 7963 | 277 | different |
| 10, 1 | visible | 770 | null (unscored) | unscored |
| 10, 2 | visible | 3897 | null (unscored) | unscored |
| 10, 3 | visible | 1698 | null (unscored) | unscored |
| 10, 4 | masked | 6116 | 7405 | different |
| 10, 5 | masked | 687 | 5750 | different |
| 10, 6 | masked | 2309 | 6954 | different |
| 10, 7 | masked | 4878 | 6456 | different |
| 10, 8 | masked | 211 | 5746 | different |
| 10, 9 | visible | 4327 | null (unscored) | unscored |
| 10, 10 | visible | 36 | null (unscored) | unscored |
| 10, 11 | visible | 6828 | null (unscored) | unscored |
| 10, 12 | visible | 6911 | null (unscored) | unscored |
| 10, 13 | visible | 2535 | null (unscored) | unscored |
| 10, 14 | visible | 5911 | null (unscored) | unscored |
| 11, 1 | visible | 7517 | null (unscored) | unscored |
| 11, 2 | visible | 8089 | null (unscored) | unscored |
| 11, 3 | visible | 6976 | null (unscored) | unscored |
| 11, 4 | visible | 6186 | null (unscored) | unscored |
| 11, 5 | visible | 8073 | null (unscored) | unscored |
| 11, 6 | visible | 6411 | null (unscored) | unscored |
| 11, 7 | visible | 4319 | null (unscored) | unscored |
| 11, 8 | visible | 4920 | null (unscored) | unscored |
| 11, 9 | visible | 7528 | null (unscored) | unscored |
| 11, 10 | visible | 5937 | null (unscored) | unscored |
| 11, 11 | visible | 2762 | null (unscored) | unscored |
| 11, 12 | visible | 7965 | null (unscored) | unscored |
| 11, 13 | visible | 6119 | null (unscored) | unscored |
| 11, 14 | visible | 2850 | null (unscored) | unscored |
| 12, 1 | visible | 960 | null (unscored) | unscored |
| 12, 2 | visible | 6959 | null (unscored) | unscored |
| 12, 3 | visible | 4035 | null (unscored) | unscored |
| 12, 4 | visible | 6950 | null (unscored) | unscored |
| 12, 5 | visible | 3741 | null (unscored) | unscored |
| 12, 6 | visible | 1672 | null (unscored) | unscored |
| 12, 7 | visible | 4878 | null (unscored) | unscored |
| 12, 8 | visible | 3542 | null (unscored) | unscored |
| 12, 9 | visible | 5540 | null (unscored) | unscored |
| 12, 10 | visible | 934 | null (unscored) | unscored |
| 12, 11 | visible | 477 | null (unscored) | unscored |
| 12, 12 | visible | 118 | null (unscored) | unscored |
| 12, 13 | visible | 6973 | null (unscored) | unscored |
| 12, 14 | visible | 2949 | null (unscored) | unscored |
| 13, 1 | visible | 4965 | null (unscored) | unscored |
| 13, 2 | visible | 7872 | null (unscored) | unscored |
| 13, 3 | masked | 523 | 6662 | different |
| 13, 4 | masked | 3669 | 1959 | different |
| 13, 5 | masked | 6053 | 3326 | different |
| 13, 6 | visible | 5751 | null (unscored) | unscored |
| 13, 7 | visible | 5701 | null (unscored) | unscored |
| 13, 8 | visible | 7851 | null (unscored) | unscored |
| 13, 9 | visible | 507 | null (unscored) | unscored |
| 13, 10 | visible | 5162 | null (unscored) | unscored |
| 13, 11 | visible | 6704 | null (unscored) | unscored |
| 13, 12 | visible | 3004 | null (unscored) | unscored |
| 13, 13 | visible | 2157 | null (unscored) | unscored |
| 13, 14 | visible | 2862 | null (unscored) | unscored |
| 14, 1 | visible | 6274 | null (unscored) | unscored |
| 14, 2 | visible | 5057 | null (unscored) | unscored |
| 14, 3 | masked | 4569 | 418 | different |
| 14, 4 | masked | 764 | 4569 | different |
| 14, 5 | masked | 6750 | 4010 | different |
| 14, 6 | visible | 5231 | null (unscored) | unscored |
| 14, 7 | visible | 5499 | null (unscored) | unscored |
| 14, 8 | visible | 5231 | null (unscored) | unscored |
| 14, 9 | visible | 4265 | null (unscored) | unscored |
| 14, 10 | visible | 7872 | null (unscored) | unscored |
| 14, 11 | visible | 6677 | null (unscored) | unscored |
| 14, 12 | visible | 6415 | null (unscored) | unscored |
| 14, 13 | visible | 2299 | null (unscored) | unscored |
| 14, 14 | visible | 5811 | null (unscored) | unscored |
Photo: Rachel Michetti · Pinned source · CC0 · Original photograph

Classification with a separate checkpoint
beit_base_patch16_224_pt22k_ft1k.pth: Self-supervised ImageNet-22K pretraining then ImageNet-1K fine-tuning; relative position bias, LayerScale, patch mean then fc_norm. This later recipe is distinct from the original 1K MIM experiment. The exact classifier crops below use shorter-edge 256, center crop 224, and normalization with mean/std 0.5. Softmax scores describe the 1,000-class distribution and are not calibrated certainty.
Chelsea the cat
- Egyptian cat (class 285)66.03%
- tiger cat (class 282)11.79%
- tabby (class 281)5.66%
- lynx (class 287)0.27%
- Angora (class 332)0.06%
Cup of coffee
- espresso (class 967)91.15%
- cup (class 968)0.96%
- coffee mug (class 504)0.10%
- consomme (class 925)0.07%
- soup bowl (class 809)0.05%
Reproduce both fixed photos with the exporter command above. Every tokenizer, masked-model and classifier logit was compared with the pinned author implementations on identical inputs, with strict weight loading. The complete comparisons, tolerances, checkpoint hashes, licenses and preprocessing are recorded in measured results and provenance. Original equation crop provenance.
- mim checkpoint · 368.4 MB · MIT (Microsoft)
- classification checkpoint · 176.8 MB · MIT (Microsoft)
- tokenizer checkpoint · 215.2 MB · Modified MIT (OpenAI)
Pinned beit_modeling_finetune.pyPinned beit_modeling_pretrain.pyPinned dall_e_utils.pyPinned dall_e_encoder.py
Keeping the tokenizer fixed makes the target representation a separate design choice. That distinction leads to BEiT-2, which changes how those visual targets are learned.
From BEiT to BEiT-3
BEiT-2 changes how visual targets are learned. VQ-KD distills a teacher representation into a quantized vocabulary instead of using the original reconstruction-trained dVAE. The pinned official release reports 85.5% for Base and 87.3% for Large at 224px with ImageNet-1K pretraining. The base result is 2.3 points above original BEiT-B's 83.2%, but the recipes differ; this comparison does not attribute the entire gain to the tokenizer alone.
BEiT-3 extends masked data modeling to vision, language and paired data. Its Multiway Transformer shares attention while using modality-specific experts; Multiway/Magneto describes the architecture, not a tokenizer. Text uses SentencePiece, and image patches and text do not share a single integer vocabulary. The pinned official release reports ImageNet-1K top-one of 85.4% for Base and 87.6% for Large at 224px, with 305M parameters in the Large vision-only classifier. These are released classification protocols, distinct from other BEiT-3 retrieval-formulation results.
How BEiT Compares
Self-Supervised Method Comparison
Published ImageNet fine-tuning results across different recipes, not a controlled benchmark. BEiT and DINO use original BEiT Table 1; MAE uses its official release, SimMIM uses ViT-B 224px/800ep, and iBOT uses released blockmask weights.
| Method | Approach | Masking | Target | ViT-B (%) | ViT-L (%) | Key Advantage |
|---|---|---|---|---|---|---|
| BEiT | Token prediction | 40% blockwise | Discrete tokens | 83.2 | 85.2 | Frozen DALL-E categorical targets, original 800ep recipe |
| MAE | Pixel reconstruction | 75% random | Raw pixels | 83.6 | 85.9 | Visible-only encoder; speed depends on recipe |
| SimMIM | Pixel reconstruction | 60% random | Raw pixels | 83.8 | — | Simple design, works with Swin Transformer |
| DINO | Self-distillation | None (multi-crop) | Teacher CLS token | 82.8 | — | Emergent segmentation in attention maps |
| iBOT | Distillation + MIM | Patch masking | Teacher tokens | 84.0 | 84.8 | Combines DINO image-level + BEiT patch-level |
| Supervised DeiT-B | Cross-entropy | N/A | Class labels | 81.8 | — | BEiT Table 1 supervised comparator, 224px |
BEiT
Frozen DALL-E categorical targets, original 800ep recipe
MAE
Visible-only encoder; speed depends on recipe
SimMIM
Simple design, works with Swin Transformer
DINO
Emergent segmentation in attention maps
iBOT
Combines DINO image-level + BEiT patch-level
Supervised DeiT-B
BEiT Table 1 supervised comparator, 224px
BEiT / DINO / DeiT sourceMAE sourceSimMIM sourceiBOT source
BEiT's key insight
- Learned categorical targets change the task from pixel regression
- Frozen dVAE maps the complete crop to a categorical grid
- Blockwise masking encourages reasoning about spatial context
Trade-offs
- Requires an externally pretrained dVAE tokenizer
- No MAE-style encoder speedup — all patches processed
- Target choice matters alongside data and training recipe
Key Results
The following are published recipes, not a controlled head-to-head experiment. Resolution, training, representation selection and model generation differ.
| Model | ImageNet fine-tuning top-one | Linear probe | Protocol |
|---|---|---|---|
| BEiT-B/16 | 83.2% | 56.7% | Original paper, 224px, 800ep; best middle-layer probe |
| BEiT-L/16 | 85.2% | — | Original paper, 224px, 800ep |
| BEiT-2 Base | 85.5% | — | Official 1K-pretrained release, 224px |
| BEiT-3 Large | 87.6% | — | Official released classifier, 224px |
| MAE ViT-B | 83.6% | 68.0% | MAE's published fine-tuning/probe recipes |
| Supervised DeiT-B | 81.8% | — | Original BEiT Table 1 comparator, 224px |
Sources: BEiT Tables 1 and 9, BEiT-2 release, BEiT-3 release, MAE release.
Why BEiT Matters
BEiT helped establish masked image modeling as a practical way to pretrain Vision Transformers. Its distinctive choice was to obtain fixed visual categories from a separately pretrained tokenizer and learn to predict them from corrupted image input. Original Table 1's BEiT-B result exceeds its supervised DeiT-B comparator by 1.4 points under the reported recipes.
The framework separates three decisions: how targets are formed, which input positions are hidden, and how the trained encoder is adapted downstream. MAE and SimMIM explore pixel targets; later BEiT work changes visual targets and extends masked modeling across modalities. The implementation makes that separation visible: target IDs come from the complete tokenizer crop, student predictions come from a masked input, and classification requires its own fine-tuned head and preprocessing.
Key Takeaways
- Two views, one spatial crop. The complete 112px tokenizer view and the masked 224px Transformer view both yield a 14×14 grid.
- Targets are categorical and frozen. DALL-E vocabulary-axis argmax supplies integer labels; student gradients do not update the tokenizer.
- Count selected positions precisely. The release requests 75 patches, may undershoot, and retains 197 encoder positions including the special token.
- Score the masked positions only. Mean cross entropy and agreement use the actual selected count; visible positions are unscored.
- Separate recipes from claims. Original MIM, later 22K-to-1K classification, and cross-paper benchmarks use different models or protocols. Token prediction alone does not guarantee semantic understanding.
Related Reading
- MAE — Masked autoencoders that reconstruct raw pixels instead of discrete tokens
- DINO — Self-distillation with Vision Transformers via momentum teacher
- SimCLR — Contrastive learning framework that established SSL baselines for vision
- MoCo — Momentum contrast for building large, consistent negative dictionaries
- I-JEPA — Joint-embedding predictive architecture that avoids pixel and token reconstruction
- DINOv2 — Scaling self-supervised ViTs with curated data and distillation
- BYOL — Bootstrap Your Own Latent — self-supervised learning without negative pairs
- VICReg — Variance-invariance-covariance regularization for non-contrastive learning