
TL;DR
- DINOv2 combines image-level DINO self-distillation, patch-level iBOT prediction and KoLeo regularization to learn visual features that transfer across several task families.
- Curated LVD-142M data and large-model training are central to the recipe. Offline distillation uses a frozen large teacher to produce smaller backbones, a separate stage from online EMA pretraining.
- A frozen backbone still needs task-specific evaluation: classification and dense prediction train downstream heads, while retrieval compares feature descriptors. Results retain their own datasets, metrics and protocols.
- The numerical training reference checks learning mechanics; the separate pretrained gallery shows saved ViT-S/14 outputs with imperfect retrieval and PCA selection. Neither reproduces the paper's benchmarks.
- Register tokens belong to a separately trained follow-up architecture. The recorded feature example uses the original no-register model.
Paper Overview
DINOv2 asks whether one self-supervised visual backbone can provide useful features for classification, segmentation, depth estimation, retrieval, and video understanding while its parameters remain frozen. DINO learns through self-distillation without contrastive negatives; masked image modeling methods such as MAE use a different objective and evaluation recipe. DINOv2 combines DINO’s image-level self-distillation with iBOT’s patch-level prediction, then scales training with curated data and distills the resulting features into smaller backbones.
Published in TMLR in 2024, the work makes three engineering contributions. It builds LVD-142M through filtering and post-processing, deduplication of the uncurated pool, and retrieval against curated sources. It trains a ViT-g/14 backbone with approximately 1.1 billion parameters, using Sinkhorn-Knopp target normalization and KoLeo regularization. It then trains ViT-S/14, ViT-B/14, and ViT-L/14 students against a frozen ViT-g/14 teacher. The original no-register models achieve 81.1%, 84.5%, 86.3%, and 86.5% ImageNet-1K validation linear-probe top-1 accuracy, respectively. These are not their k-NN scores. See Table 4, p. 12 and the official model table.
The central result is broad transfer from a frozen backbone. For classification and dense prediction, the evaluation still trains task-specific heads with labeled downstream data. “Without backbone fine-tuning” therefore does not mean “without adaptation” or “without downstream supervision.” To understand how those features are learned, start with the two training signals.
Combined Training Objective
The image-level DINO loss gives the student 2 global + 8 local crops while the online momentum-updated teacher processes only the 2 unmasked global crops. The selected patch-14 recipe uses 224×224 global and 98×98 local crops; the generic code default is 224/96 with patch size 16. The crop area ranges are 0.32–1.0 global and 0.05–0.32 local, before resizing. The original DINO paper Appendix describes 2 global + 6 local crops, a separate convention. The student’s [CLS] token representations pass through a projection head; their prototype distributions match teacher soft targets through cross-entropy across different views. See the pinned default config and ViT-g/14 recipe.
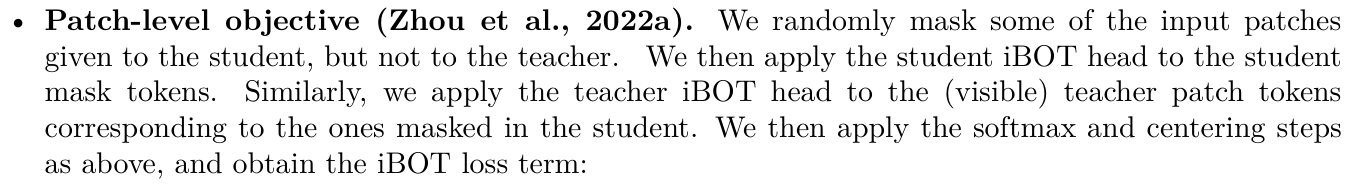
The patch-level iBOT loss masks patches in selected student global-crop entries. Local crops remain unmasked. The student predicts teacher prototype distributions at those masked positions, using a separate iBOT head; teacher targets come from the corresponding visible patches in the unmasked global view. The released default selects global entries for masking with probability 0.5 and samples mask ratios between 0.1 and 0.5. The displayed optimization objective includes the feature regularizer:
where w_D, w_I, w_K weight the three terms. The DINO component aligns image-level semantics across crops; iBOT supervises selected spatial positions. KoLeo encourages normalized image features to spread within a batch. Together these signals support transfer to both image-level and dense tasks; the downstream heads determine how features become task predictions.
To reduce collapse risk, Sinkhorn-Knopp alternates normalization of teacher assignments for 3 iterations, encouraging approximately balanced prototype usage within the batch. A finite iteration count does not guarantee exact uniform marginals. The paper Appendix describes KoLeo on the first global crop. The released code evaluates both global chunks separately and sums their per-crop terms into the optimization loss; division by two is used for the logged metric average. The existing lineage CPU toy uses 2 global + 2 local crops and averages its two per-crop KoLeo terms; it remains a separate illustration. See Section 4 and Appendix B and the pinned training loop.
Data Curation at Scale
A central thesis of DINOv2 is that data diversity and quality matter alongside the objective. The paper combines curated source datasets with web images selected by visual similarity, rather than training indiscriminately on every downloaded image. Pretraining uses images, not class labels or text captions, even though some curated source datasets contain labels.
The pipeline has three ordered stages. First, filter and post-process raw inputs. Second, deduplicate the uncurated pool. Third, retrieve and match against curated source datasets, using candidates from that filtered, deduplicated pool. The preprocessed pool contains 1.2 billion unique images; subsequent copy detection also removes near-duplicates and overlaps with evaluation sets. Retrieval then yields LVD-142M. Its retrieval encoder is a self-supervised ViT-H/16 pretrained on ImageNet-22k, not the DINOv2 model still to be trained. Large query datasets typically retrieve 4 neighbors per image; small query datasets use cluster sampling. See Section 3, pp. 4–5.
The data ablation does not show a universal 2–3 point classification gain. In Table 2, p. 8, ImageNet-1K changes from 85.9 to 85.8 when switching from ImageNet-22k to LVD-142M, while ADE20K improves from 46.6 to 47.7 and Oxford-Medium from 62.5 to 64.6. These are separate task metrics from shorter ablation runs without high-resolution adaptation, not the final released-model scores. The gains in other domains motivate curated diversity while keeping the ImageNet result roughly stable. Original data ablation.
Model Distillation
A ViT-g/14 teacher is expensive to deploy, so DINOv2 uses offline knowledge distillation. Train smaller student backbones against a frozen larger teacher. This stage differs from the online EMA teacher of self-supervised pretraining. Section 5 removes masking and stochastic depth for distillation, applies iBOT on the two global crops, and keeps a separate EMA of the student for the final evaluated model. Model distillation, p. 7.
The useful comparison is the absolute linear-probe accuracy gap in one setting: ViT-S/14 at 81.1% is 5.4 percentage points below ViT-g/14; ViT-B/14 at 84.5% is 2.0 points below; ViT-L/14 at 86.3% is 0.2 points below. The official model table rounds their parameter counts to 21M, 86M, and 300M, versus 1,100M for ViT-g/14. Figure 5 separately compares distilled ViT-L against training it from scratch across 12 benchmarks; the distilled student sometimes exceeds its teacher. Neither that ablation nor ratios of accuracy establish a universal “performance retained” percentage. Table 4 and Figure 5 and official models.
Implementation
The objectives above describe how DINOv2 learns; distillation explains how its smaller backbones become practical. Here we connect original paper details to tensor operations and executable Python, then inspect actual outputs from the released ViT-S/14. Follow the sequence, or jump to Inspect the training mechanism and Use pretrained features.
The numerical training reference uses seeded image tensors and a tiny encoder to verify losses, gradients, and one teacher update. The pretrained feature program uses official LVD-142M weights on nine NASA photographs. The short training run does not produce these gallery features.
Context matters: Earthrise is the first neighbor of an astronaut query. These positive-side patch colors mostly retain lunar terrain, rather than isolating the astronauts. The galleries below expose every query and both PCA threshold sides.
Inspect the training mechanism
Let B = 4 images, L = 8 local views, C = 2 + L = 10 student views, N = 64 global patches, D = 64 feature channels, and K = 32 prototypes. The torch-only reference uses CPU float64 by default. Its two-block, four-head encoder has patch size 8, global/local resolutions 64/32, a normalized 16-dimensional head bottleneck, and separate CLS/patch heads. These small dimensions and fixed schedules are teaching choices, not released-model dimensions.
Which views are seen, and where is information hidden?
Original paper
The teacher sees clean global crops; only selected student global entries are masked. Appendix B.1 supplies the larger training recipe. Open original detail at full size.
Math and tensor shapes
Two global crops share geometry between student and teacher. Eight local student views stay unmasked. Global inputs have shape [2B,3,64,64]; local inputs are [LB,3,32,32].
The boolean mask is [2B,N] = [8,64]. Half the global image entries are selected; their seeded mask ratios lie in [0.1,0.5]. All other entries contain zero masked positions.
Inside the full backbone, learned mask tokens replace the selected patch embeddings before attention. The fixture uses readable random masks and tensor crops; it simplifies the released block-mask sampler and color augmentation pipeline.
Python implementation
# Globals come first. The clean teacher reuses these exact image tensors.
views = []
for size in [64, 64] + [32] * config.local_crops:
    offsets = torch.randint(
        0, 81 - size, (config.batch_size, 2), generator=generator
    )
    crops = torch.stack(
        [
            image[:, top : top + size, left : left + size]
            for image, (top, left) in zip(images, offsets.tolist())
        ]
    )
    views.append(crops.to(config.device))
masks = torch.zeros(2 * config.batch_size, 64, dtype=torch.bool)
selected_entries = torch.randperm(
    2 * config.batch_size, generator=generator
)[: config.batch_size]
for entry in selected_entries:
    ratio = 0.1 + 0.4 * torch.rand((), generator=generator).item()
    indices = torch.randperm(64, generator=generator)[: int(64 * ratio)]
    masks[entry, indices] = True
return views, masks.to(config.device)
How do features become training targets?
Original paper
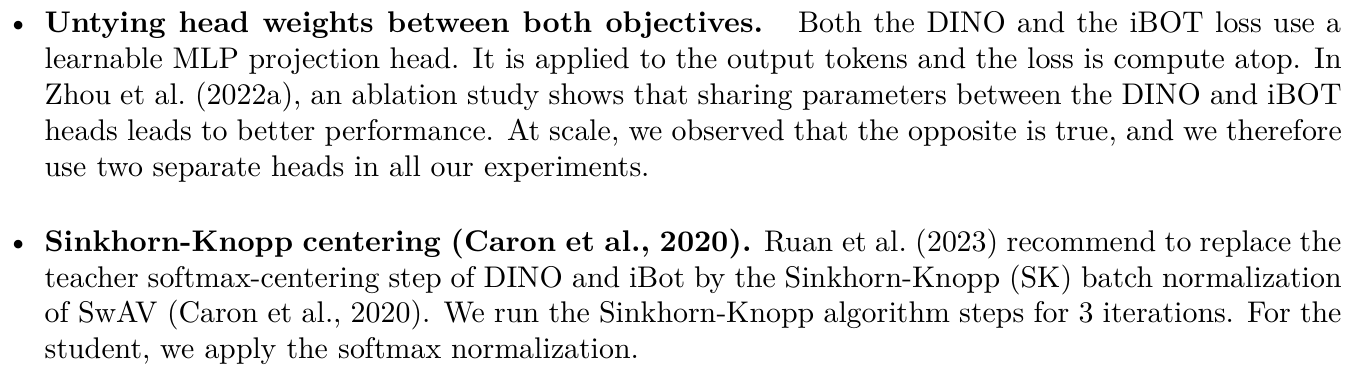
Original head separation and Sinkhorn passage. We select the pinned ViT-g recipe, rather than the repository-wide shared-head / mean-centering default. Open original detail at full size.
Math and tensor shapes
Teacher CLS features [2B,D] and patch features [2B,N,D] pass through separate projection heads. Their output scores are over K prototypes, not feature channels.
Run three log-domain Sinkhorn iterations separately on [2B,K] and [M,K], where M is the total masked count. Targets are detached, row-normalized prototype distributions. Three iterations only approximate a uniform prototype marginal; the report records its remaining imbalance.
With M = 0, skip patch Sinkhorn. The teacher and target construction receive no gradients. Additional implementation reference: released CLS target construction.
Python implementation
with torch.no_grad():
    teacher_globals = model.teacher["backbone"](globals_)
    cls_scores = model.teacher["cls_head"](teacher_globals["cls"])
    cls_targets = sinkhorn_targets(cls_scores, 0.07, iterations=3)
    patch_scores = model.teacher["patch_head"](teacher_globals["patches"])[
        masks
    ]
    # M=0 must bypass Sinkhorn, whose normalization needs nonempty samples.
    patch_targets = (
        sinkhorn_targets(patch_scores, 0.07, iterations=3)
        if patch_scores.shape[0]
        else patch_scores.new_empty((0, 32))
    )
Which image views should agree?
Original paper
Original unnumbered DINO equation (our derivation abbreviates its loss as L_D). Its probabilities are over prototypes; cross-view pairing is made explicit in our derivation.
Math and tensor shapes
For teacher view t ∈ {0,1} and student view s ∈ {0,…,C−1}, exclude the matching global view s = t. This leaves 2(C−1) = 18 valid pairs.
Each pair compares [B,K] targets and predictions, averages over its images, then the code averages the valid pairs. The full function uses log_softmax on the temperature-scaled scores before this excerpt; the expectation notation averages over pairs and images.
Python implementation
losses = [
    -(teacher_targets[t].detach() * log_probabilities[s]).sum(-1).mean()
    for t, s in dino_pairs(len(student_logits) - 2)
]
return torch.stack(losses).mean()
Which patch predictions contribute?
Original paper
Original unnumbered iBOT equation. The following page defines the indices as masked patches; reduction weights come from the released implementation.
Math and tensor shapes
Teacher and student use exactly the same (global view, image, patch) indices. Boolean gathering changes scores from [2B,N,K] to [M,K].
A zero-mask entry contributes zero but still appears in the 2B denominator. An entirely empty mask returns a differentiable zero. The reciprocal mask count gives each masked image entry equal weight, rather than weighting by its number of patches.
Additional implementation reference: released masked-patch reduction.
Python implementation
selected = student_logits[masks]
_targets(teacher_targets, student_logits, (selected.shape[0], prototypes))
if selected.shape[0] == 0:
    return selected.sum()
log_probabilities = F.log_softmax(
    _scaled_logits(selected, temperature), dim=-1
)
patch_losses = -(teacher_targets.detach() * log_probabilities).sum(-1)
weights = masks.sum(-1).clamp(min=1).to(student_logits.dtype).reciprocal()
gathered_weights = weights[:, None].expand_as(masks)[masks]
return (patch_losses * gathered_weights).sum() / entries
Why spread image features apart?
Original paper
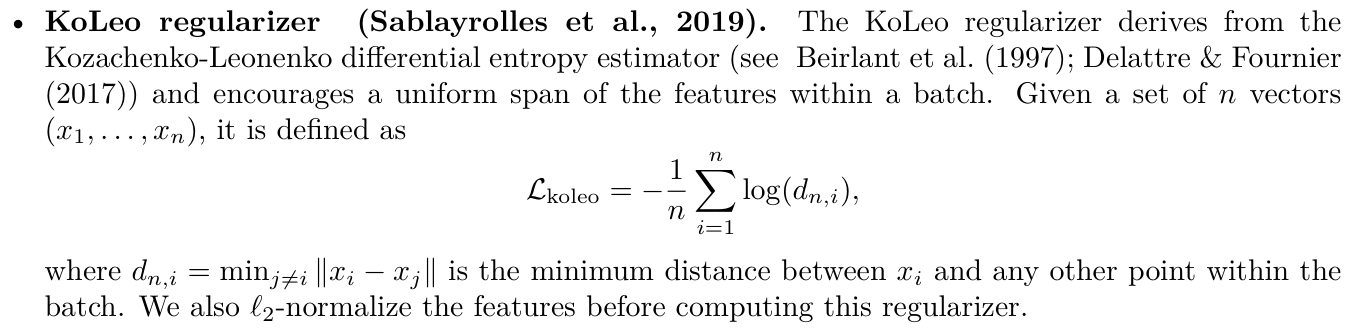
Original KoLeo equation (our derivation abbreviates its loss as L_K). The released code supplies the epsilon convention and per-view operation. Open the original KoLeo passage at full size.
Math and tensor shapes
Use student CLS backbone features before the heads, shaped [B,D] within each global view. Normalize them, exclude self, and choose the nearest other image by maximum cosine similarity.
Here d_i uses pairwise_distance with eps = 1e−8. Compute this separately for the two global-view batches. Concatenating them changes the neighbor candidates. A distance above one can give a negative loss; the requirement is finite values.
Additional implementation reference: released epsilon-distance operation.
Python implementation
epsilon = 1e-8
normalized = F.normalize(features, p=2, dim=-1, eps=epsilon)
similarities = normalized @ normalized.t()
# Unlike a -1 sentinel, -inf excludes self even for antipodal ties.
similarities.fill_diagonal_(-math.inf)
neighbors = similarities.argmax(dim=-1)
distances = F.pairwise_distance(
    normalized, normalized[neighbors], p=2, eps=epsilon
)
return -(distances + epsilon).log().mean()
What changes after backpropagation?
Original paper
Original EMA update passage. The full released loop updates backbone and projection heads after the student optimizer step. Open original detail at full size.

Math and tensor shapes
Here L_D is DINO and L_I is iBOT.
Backpropagate the summed objective and update only the student with AdamW: lr = 1e−3, weight_decay = 0.04, betas = (0.9,0.999). The KoLeo display average is distinct from the sum used for optimization.
The teacher starts as a deep copy in evaluation mode. After the optimizer step, update every corresponding teacher parameter using the updated student, including both heads. This numerical reference keeps momentum fixed; the full recipe schedules it.
Additional implementation reference: released objective and teacher update.
Python implementation
objective["total"].backward()
optimizer.step()
# Every backbone and head parameter: m*old_teacher + (1-m)*updated_student.
ema_update(model.teacher, model.student, momentum)
The online EMA teacher above checks the pretraining mechanism. Offline distillation then uses a frozen large teacher, removes masking, and evaluates an EMA of the smaller student, as described in Section 5, p. 7. The next program loads that released smaller backbone; it does not distill it again. Its real-image results come from the official checkpoint, independently of our one-step numerical run.
Use pretrained features
What does the released backbone return?
Original paper
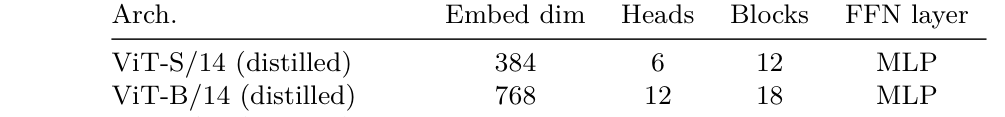
Original architecture detail: the distilled ViT-S/14 has width 384. The pinned released feature API defines the returned token names. Open original detail at full size.
Math and tensor shapes
The original no-register dinov2_vits14 loads official LVD-142M weights in evaluation and inference mode. It uses CPU float32 by default; PCA later runs on CPU float64.
Apply RGB/EXIF handling, resize the short edge to 256 with bicubic interpolation, center-crop 224, and normalize with ImageNet mean/std. The saved 224 × 224 crop is exactly what the encoder sees. Patch size 14 gives a 16 × 16 grid.
These final backbone features differ from training scores over 32 prototypes. This program uses neither training projection head. Additional implementation reference: released feature API.
Python implementation
result = model.forward_features(
    tensor.unsqueeze(0).to(device=device, dtype=torch.float32)
)
cls_features.append(result["x_norm_clstoken"].cpu())
patch_features.append(result["x_norm_patchtokens"].cpu())
Which gallery images resemble a query?
Original paper
Original instance-recognition passage. Our gallery illustrates cosine ranking; it is not a reproduction of benchmark mAP. Open original detail at full size.
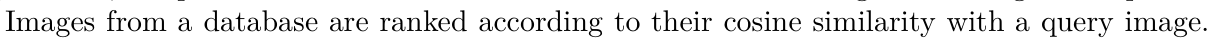
Math and tensor shapes
L2-normalize the saved CLS vector of each gallery image. A query scores every other image by cosine similarity.
Exclude the query itself and sort descending. Stable image IDs break equal-score ties. The gallery exposes four saved neighbors and three-decimal scores, while the export retains full precision.
No labels are used in the score. A curated subject group is descriptive metadata, so a terrain-rich Earthrise image can outrank another astronaut photo.
Python implementation
normalized = vectors / norms
similarities = normalized @ normalized.T
queries = {}
for index, query in enumerate(image_ids):
    neighbors = [
        {"imageId": image_id, "score": similarities[index, other].item()}
        for other, image_id in enumerate(image_ids)
        if other != index
    ]
    queries[query] = sorted(
        neighbors, key=lambda row: (-row["score"], row["imageId"])
)Query g1-01: 4 saved neighbors, ranked by cosine similarity.
#1 · 0.519Earthrise from Apollo 11g3-03 · NASA / Apollo 11 crew #2 · 0.462Buzz Aldrin on the Moong1-02 · NASA / Neil A. Armstrong #3 · 0.355Charles Conrad on the Moong1-03 · NASA / Apollo 12; photographer not individually credited #4 · 0.307Earth from Apollo 17, second viewg3-02 · NASA / Apollo 17 crew
These nine NASA photographs form a small similarity demonstration. Shared terrain or background can outrank the curated subject. Scores are rounded to three decimals here; the manifest retains full precision. NASA media usage guidelines apply to the linked originals.
What variation is visible in patch features?
Original paper
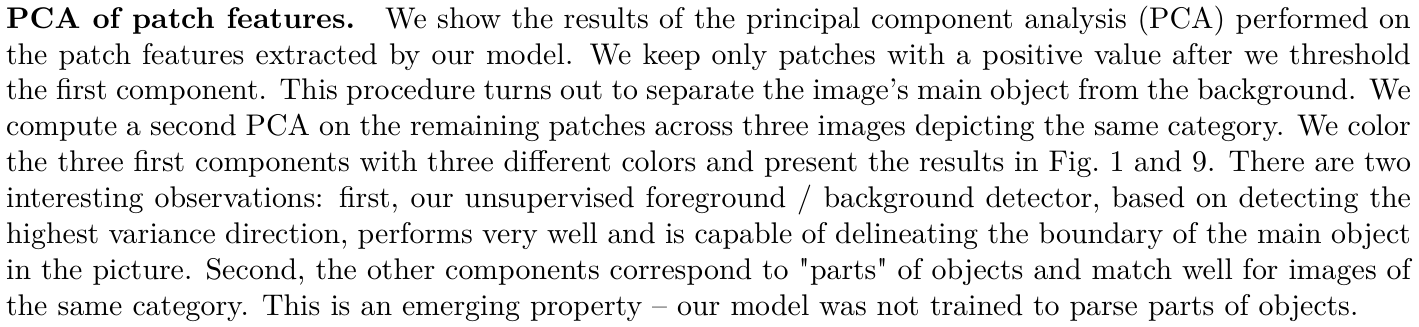
Cropped original Figure 1(b): related images share PCA component colors. Open the original Section 7.5 PCA passage at full size.
Math and tensor shapes
Stack three related images into A: [768,384]. Center the raw final-layer patch features and fit a first component across the entire group.
Orient the largest absolute loading positively. This stabilizes the sign; it does not name foreground. Scores at zero belong to neither side. For each retained side, fit its own centered three-component PCA across all selected patches.
Scale each RGB channel with one group-wide min/max and restore the scores to 16 × 16 patch grids. Removed patches have alpha zero; constant channels use a neutral midpoint. Colors are comparable within a group and side only.
Fewer than four retained patches or fewer than three nonzero directions yields a descriptive failure status instead of a color image. The complete source excerpt includes those cases. Original Figure 1 and full caption.
Python implementation
first_basis = _fit_basis(rows, 1)
first_scores = ((rows - first_basis["mean"]) @ first_basis["loadings"].T)[
    :, 0
]
variants = {}
for side in ("positive", "negative"):
    mask = (
        first_scores > threshold
        if side == "positive"
        else first_scores < threshold
    )
    retained = rows[mask]
    variant = {
        "masks": mask.reshape(len(image_ids), 16, 16),
        "retainedCount": len(retained),
        "secondBasis": None,
    }
    if first_basis["rank"] == 0:
        variant.update(
            status="degenerate_features",
            message="The shared first PCA has no nonzero direction.",
        )
    elif len(retained) < 4:
        variant.update(
            status="insufficient_foreground",
            message="This threshold side retains fewer than four patches.",
        )
    else:
        second_basis = _fit_basis(retained, 3)
        variant["secondBasis"] = second_basis
        if second_basis["rank"] < 3:
            variant.update(
                status="degenerate_features",
                message=(
                    "The retained patches have fewer than three "
                    "nonzero PCA directions."
                ),
            )
        else:
            scores = (retained - second_basis["mean"]) @ second_basis[
                "loadings"
            ].T
            colors = scale_rgb(scores)
            rgba = torch.zeros(len(rows), 4, dtype=torch.uint8)
            rgba[mask, :3] = colors
            rgba[mask, 3] = 255
            variant.update(
                status="ok",
                message=(
                    "Separate shared PCA fitted to this retained "
                    "threshold side."
                ),
                rgba=rgba.reshape(len(image_ids), 16, 16, 4),
                channelMin=scores.amin(dim=0),
                channelMax=scores.amax(dim=0),
            )
variants[side] = variantApollo astronauts, positive side: 359 of 768 patches retained. Separate shared PCA fitted to this retained threshold side.
Alan Bean on the Moon
Encoded crop · 224 × 224
RGB components · 16 × 16
Gray: removed patches
Mask · white retained
black removed
Buzz Aldrin on the Moon
Encoded crop · 224 × 224
RGB components · 16 × 16
Gray: removed patches
Mask · white retained
black removed
Charles Conrad on the Moon
Encoded crop · 224 × 224
RGB components · 16 × 16
Gray: removed patches
Mask · white retained
black removed
The positive side mostly retains lunar terrain. The negative side mostly selects the dark upper areas; neither neatly isolates the astronauts. The loading sign is a numerical convention, not a semantic foreground label.
Each side has a separately fitted shared PCA and group-wide RGB scaling. Colors can be compared only within the selected group and side; they are not class labels. Patch grids use nearest-neighbor enlargement against a neutral gray background.
Original paper details are cropped, without retouching, from Oquab et al., DINOv2, published in TMLR. Original published record, TMLR CC BY 4.0 policy, and license. The paper captions identify each section and printed page; the DINO and iBOT equations are unnumbered. Our mathematical reductions and Python excerpts appear in their own columns.
Run the numerical reference
Download dinov2_training_core.py and training requirements. The default run is offline and torch-only after installation. The requirements record a qualified Python 3.13.13 CPU environment; fixed seed 7 and one step produce an inspectable numerical receipt.
python -m pip install -r requirements-dinov2-training.txt
python dinov2_training_core.py --device cpu --seed 7 --steps 1 --report-json training-report.json
The report records view IDs and shapes, mask counts, 18 DINO pairs, individual losses and the optimized total, Sinkhorn marginal imbalance, gradient norms for the student backbone, heads and mask token, the teacher gradient count, and the maximum EMA update error. It measures routing and mathematical behavior, not image accuracy. Saved training receipt.
Run the released-feature example
Download dinov2_features.py, feature requirements, and the nine-image sample archive. Unzip the archive into dinov2-sample-images/, preserving its manifest.json, images/, and LICENSES.md. The first online run fetches pinned official code and weights. These exact Python pins were qualified on CPU: torch 2.12.0, torchvision 0.27.0, NumPy 2.1.2, and Pillow 12.2.0.
python -m pip install -r requirements-dinov2-features.txt
python dinov2_features.py --images dinov2-sample-images --output feature-output --device cpu
To use local-only loading, supply both a checkout at revision 7764ea0f912e53c92e82eb78a2a1631e92725fc8 and the official ViT-S/14 weight file. The program validates the revision and loads the weights strictly. The saved canonical export was produced with CPU float32 inference and CPU float64 PCA; it also has a verified offline run.
python dinov2_features.py --images dinov2-sample-images --output feature-output-offline --device cpu --repo-dir /path/to/dinov2 --weights /path/to/dinov2_vits14_pretrain.pthOutput includes encoded crops, CLS and patch tensors, full retrieval rankings, both threshold-side masks and PCA images, model/runtime metadata, source checksums, and artifact hashes. Use a fresh output directory. The supplied gallery also produces a sample ZIP from its own manifest, images, and license notes, even when the gallery is in another folder. Your own photo folder needs no sample download: its export has sampleArchive: null and no sample ZIP. Source checksums describe the running script and include the requirements file only when it is beside the script. A reader image directory may contain 3–64 images, each bounded to 25 megapixels; corrupt files fail visibly rather than silently changing the gallery. Without the sample manifest, the first three sorted image IDs form the default PCA group; --pca-images selects another group of at least three IDs.
Inspect the canonical feature manifest and feature tensor artifact. The page reads saved exports: it downloads no model into the browser and performs no feature computation when a control changes.
The numerical receipt establishes the learning mechanism; the small gallery demonstrates feature use and exposes imperfect retrieval and foreground selection. Neither is a benchmark reproduction. The next section returns to the paper’s published evaluations, with their original datasets, metrics, and trained-head protocols.
Universal Feature Quality
The evaluation attaches trained linear or decoder heads to frozen DINOv2 backbones for classification and dense prediction. Retrieval instead compares frozen feature descriptors. The results demonstrate broad transfer, but each task has its own dataset, metric, and protocol. The paper also evaluates video recognition; the interactive comparison below retains that choice without substituting an unsupported generic percentage.
On ImageNet-1K validation linear probing at 224px, DINOv2 ViT-g/14 achieves 86.5%, compared with 79.2% for DINO ViT-S/8, 76.6% for MAE ViT-H/14, 84.3% for CLIP ViT-L/14, and 86.2% for OpenCLIP ViT-G/14 (Table 4, p. 12). On ADE20K validation with a single-scale linear head, the same DINOv2 backbone reaches 49.0 mIoU, compared with 31.8 for DINO ViT-B/8, 33.3 for MAE ViT-H/14, and 39.3 for OpenCLIP ViT-G/14 (Table 10, p. 15). DINO’s architecture differs between those tables.
On NYUd test with a linear depth head using one transformer layer, DINOv2 ViT-g/14 has 0.344 m RMSE, where lower is better (Table 11, p. 16). On Revisited Oxford-Hard retrieval, it reaches 52.3% mAP; ViT-L/14 reaches 54.0%, so the largest backbone does not win every setting (Table 9, p. 14). Scores from different metrics or decoder recipes cannot be averaged into a meaningful overall advantage.
Register Tokens
The follow-up Vision Transformers Need Registers studies high-norm patch outliers in large ViTs. Such patches can hold global information while losing local detail, often appearing in redundant background regions. The authors propose that models use these patches for internal computation.
Their remedy adds learnable register tokens during training, then discards register outputs when extracting CLS and patch features. The experiments use 4 registers and produce smoother attention and feature maps. Appending untrained registers at inference is not the demonstrated procedure.
The reported benefits depend on the model and task, rather than a universal 1–2 point gain. The widget below is a seeded schematic, not attention measured from a released checkpoint; switching modes illustrates separately trained architectures. Its spike counts, attention values, and spread labels are illustrative. The released-feature example uses the original no-register ViT-S/14. Follow-up Sections 2.2–3.2.
How DINOv2 Compares
Self-Supervised Method Comparison
How DINOv2 compares to other self-supervised and vision-language approaches using the paper's actual model architectures. ImageNet-1K validation linear top-1 accuracy at 224px (Table 4, p. 12) and ADE20K validation single-scale linear mIoU (Table 10, p. 15) use trained heads on frozen backbones. CLIP has no dense result in the selected table. These are not matched-size comparisons.
Original paper Tables 4 and 10
| Method | Training Signal | Data | ImageNet-1K Linear (%) | ADE20K Linear (mIoU) | Key Advantage |
|---|---|---|---|---|---|
| DINOv2 | DINO + iBOT + KoLeo | LVD-142M | 86.5DINOv2 ViT-g/14 | 49.0DINOv2 ViT-g/14 | Strong frozen image-level and dense features in these settings |
| DINO | Self-distillation | ImageNet-1K | 79.2DINO ViT-S/8 | 31.8DINO ViT-B/8 | Emergent spatial structure in self-attention maps |
| MAE | Pixel reconstruction | ImageNet-1K | 76.6MAE ViT-H/14 | 33.3MAE ViT-H/14 | Masked reconstruction pretraining |
| CLIP | Contrastive (image + text) | WIT-400M | 84.3CLIP ViT-L/14 | Unavailable | Text-prompt transfer; dense result unavailable in Table 10 |
| OpenCLIP | Contrastive (image + text) | LAION-2B | 86.2OpenCLIP ViT-G/14 | 39.3OpenCLIP ViT-G/14 | Open-source vision-language features |
| iBOT | DINO + masked prediction | ImageNet-22K | 82.3iBOT ViT-L/16 | 44.6iBOT ViT-L/16 | Image-level and patch-level objectives |
DINOv2
Strong frozen image-level and dense features in these settings
DINO
Emergent spatial structure in self-attention maps
MAE
Masked reconstruction pretraining
CLIP
Text-prompt transfer; dense result unavailable in Table 10
OpenCLIP
Open-source vision-language features
iBOT
Image-level and patch-level objectives
DINOv2's key insight
- Combining DINO + iBOT objectives yields features that excel at both image-level and pixel-level tasks
- Curated LVD-142M selects diverse images from a filtered, deduplicated web pool
- No text supervision needed — purely visual pretraining uses image-only objectives; downstream heads use labels
Trade-offs
- Requires massive compute for ViT-g training — not reproducible without significant resources
- No zero-shot text-based transfer — unlike CLIP, cannot classify with text prompts
- Data curation pipeline adds complexity — seed dataset selection affects downstream quality
Key Results
These tables use the same source-backed records as the widgets. Each column is a separate named evaluation setting, with a frozen backbone; percentages, mIoU, and depth RMSE stay in their original units.
| Model | ImageNet-1K validation, linear probe at 224pxTop-1 accuracy (%), higher is betterTable 4, p. 12 | ADE20K validation, linear head (single scale)mIoU (%), higher is betterTable 10, p. 15 | NYUd test, linear head on one transformer layerRMSE (m), lower is betterTable 11, p. 16 |
|---|---|---|---|
| DINOv2 ViT-g/14 | 86.5DINOv2 ViT-g/14 | 49.0DINOv2 ViT-g/14 | 0.344 mDINOv2 ViT-g/14 |
| DINOv2 ViT-L/14 | 86.3DINOv2 ViT-L/14 | 47.7DINOv2 ViT-L/14 | 0.384 mDINOv2 ViT-L/14 |
| DINOv2 ViT-B/14 | 84.5DINOv2 ViT-B/14 | 47.3DINOv2 ViT-B/14 | 0.399 mDINOv2 ViT-B/14 |
| DINOv2 ViT-S/14 | 81.1DINOv2 ViT-S/14 | 44.3DINOv2 ViT-S/14 | 0.449 mDINOv2 ViT-S/14 |
| DINO | 79.2DINO ViT-S/8 | 31.8DINO ViT-B/8 | 0.555 mDINO ViT-B/8 |
| MAE | 76.6MAE ViT-H/14 | 33.3MAE ViT-H/14 | 0.517 mMAE ViT-H/14 |
| OpenCLIP | 86.2OpenCLIP ViT-G/14 | 39.3OpenCLIP ViT-G/14 | 0.541 mOpenCLIP ViT-G/14 |
Why DINOv2 Matters
DINOv2 demonstrates that combining image-level and patch-level objectives, curating diverse pretraining data, and distilling a large teacher can produce backbones that transfer across several task families. Its frozen features are strong baselines; the paper’s results do not establish that every model size beats every alternative on every dataset.
For practitioners, this supports a practical workflow: reuse the pretrained backbone, select a suitable downstream representation, and train the task head. That can reduce the work required compared with training a backbone from scratch, while the smaller distilled models offer different compute budgets. The next question is whether the selected evaluation recipe and training data match the intended application.
Key Takeaways
-
DINO and iBOT supervise different representations — image-level prototype targets and selected masked global patches; KoLeo is also part of the optimized objective.
-
Data curation has an explicit order — filter and post-process, deduplicate the uncurated pool, then retrieve against curated sources to produce LVD-142M.
-
Distillation has a small measured gap for ViT-L — 86.3% versus 86.5% ImageNet-1K linear-probe accuracy, an absolute 0.2 percentage-point difference, with roughly 300M versus 1,100M parameters.
-
Registers are a trained follow-up architecture — four extra tokens provide space for internal computation; the illustrative toggle does not retrofit released weights.
-
Frozen-backbone evaluation still trains task heads — 86.5% ImageNet-1K linear probing, 49.0 ADE20K linear mIoU, and 0.344 m NYUd lin. 1 RMSE describe three distinct settings, not one universal score.
Related Reading
- DINO — Self-distillation with Vision Transformers, the image-level objective that DINOv2 builds upon
- MAE — Masked autoencoders for pixel reconstruction, complementary to DINOv2’s iBOT component
- BEiT — Discrete visual token prediction that pioneered masked image modeling
- I-JEPA — Joint-embedding prediction without reconstruction, an alternative to masked modeling
- SimCLR — Contrastive learning framework, a different objective from DINO self-distillation
- MoCo — Momentum contrast, the architectural precursor to DINO’s momentum teacher
- BYOL — Non-contrastive learning without negatives, influencing DINO’s asymmetric design
- VICReg — Variance-invariance-covariance regularization, an alternative non-contrastive approach